Choosing The Best PC For Running LLMs Locally
Running large language models (LLMs) locally requires a PC with sufficient RAM, a powerful CPU, and ideally a GPU for acceleration. For most consumer-grade LLMs (like Llama 2 7B or Mistral 7B), a minimum of 16GB RAM is recommended, with 32GB or more being ideal for larger models. The CPU should have high single-core performance and multiple cores to handle token generation efficiently. While integrated graphics can run smaller quantized models, a dedicated NVIDIA GPU with at least 8GB VRAM significantly improves inference speed and enables larger models.
Key Specifications For Local LLM Performance
For optimal LLM performance, prioritize systems with:
-
RAM: 16GB minimum (for 7B models), 32GB+ recommended (for 13B+ models)
-
CPU: Intel Core i5/i7 (12th gen or newer) with high clock speeds and multiple cores
-
Storage: Fast NVMe SSD (512GB+) for model files and datasets
-
GPU: NVIDIA RTX 3060 or better (8GB+ VRAM) for GPU acceleration
Without a dedicated GPU, CPU-only inference is possible using tools like llama.cpp, but will be significantly slower. Quantized models (4-bit or 8-bit) reduce memory requirements and run on lower-spec hardware.
Recommended Thinvent Models For LLM Tasks
Based on the available products, the best options for running LLMs locally are the higher-end Intel-based models:
| Model | Processor | RAM | Storage | Best For |
|---|---|---|---|---|
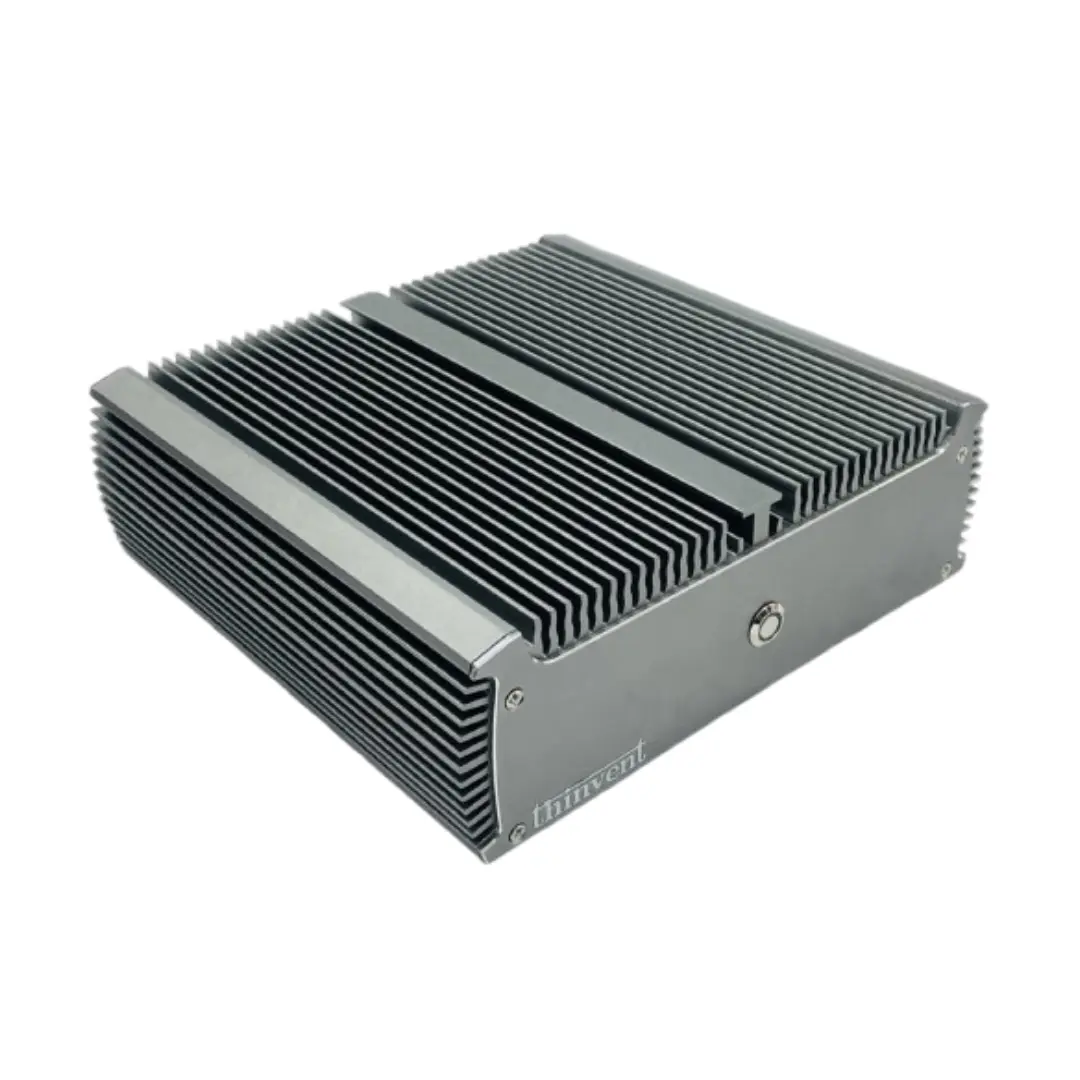
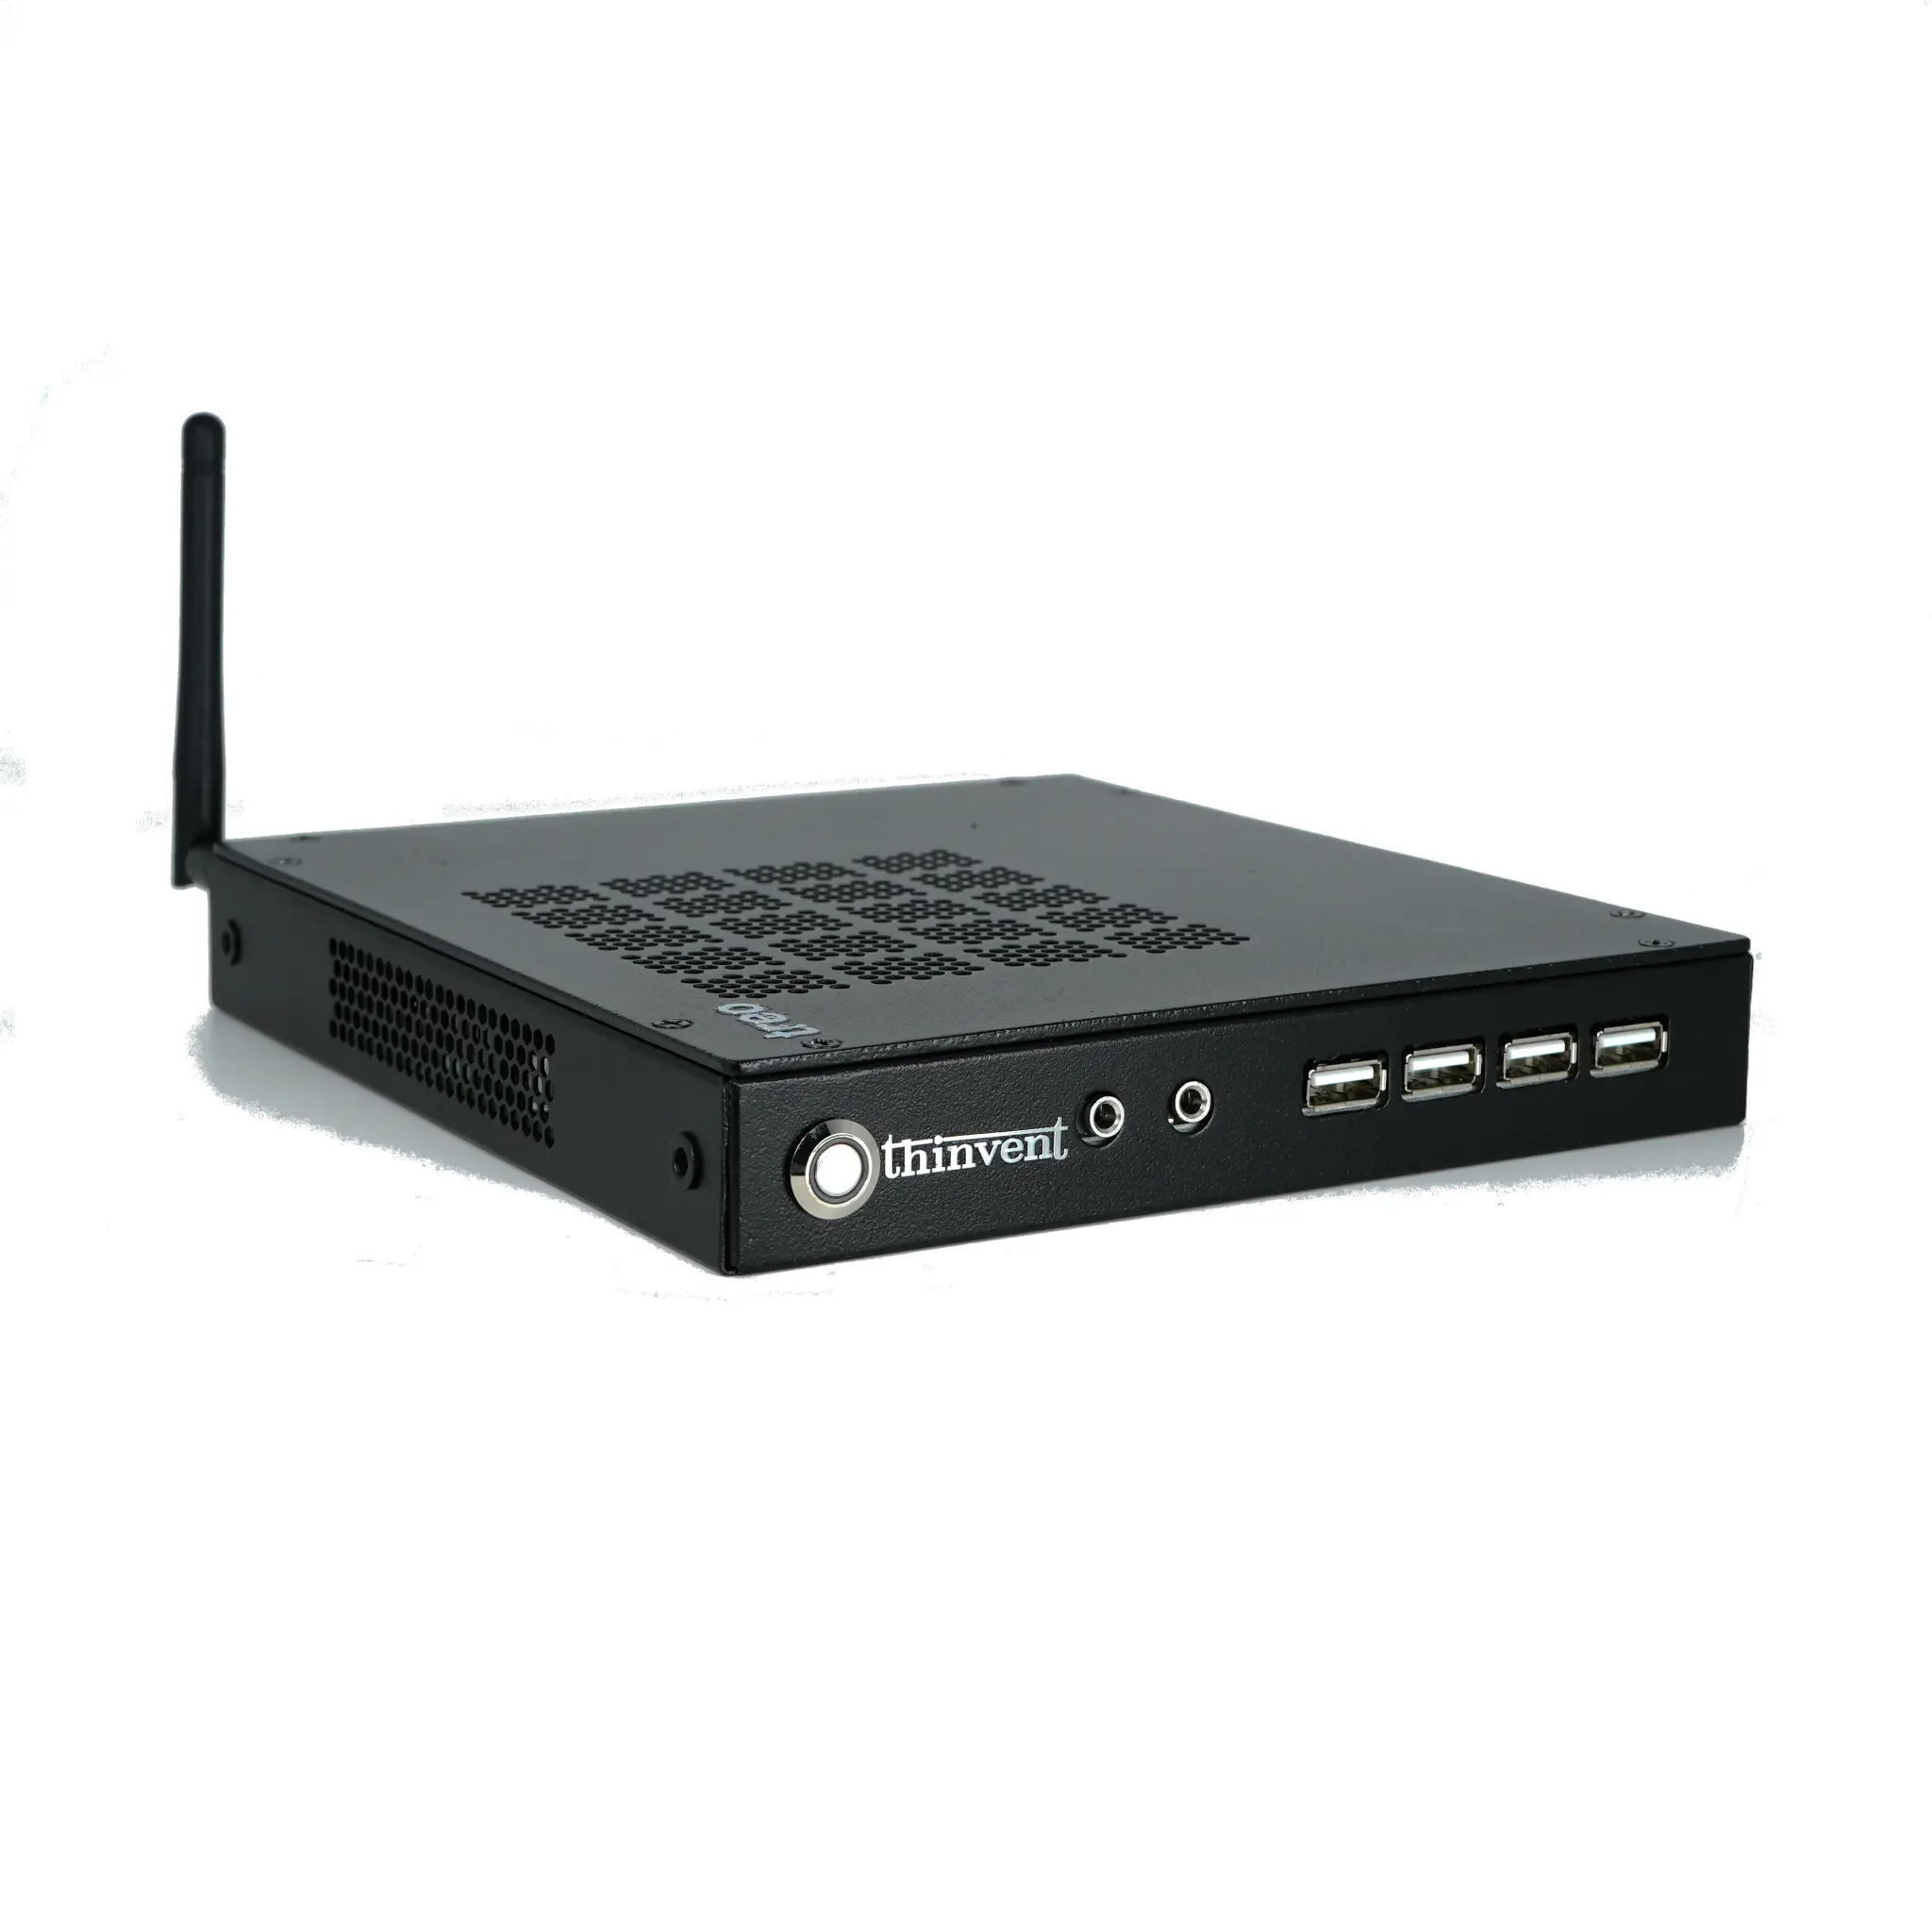
| Thinvent Aero Mini PC (14th Gen) | Core 5 120U (10 cores, 5.0 GHz) | 16GB | 512GB SSD | Small LLMs (7B quantized), inference |
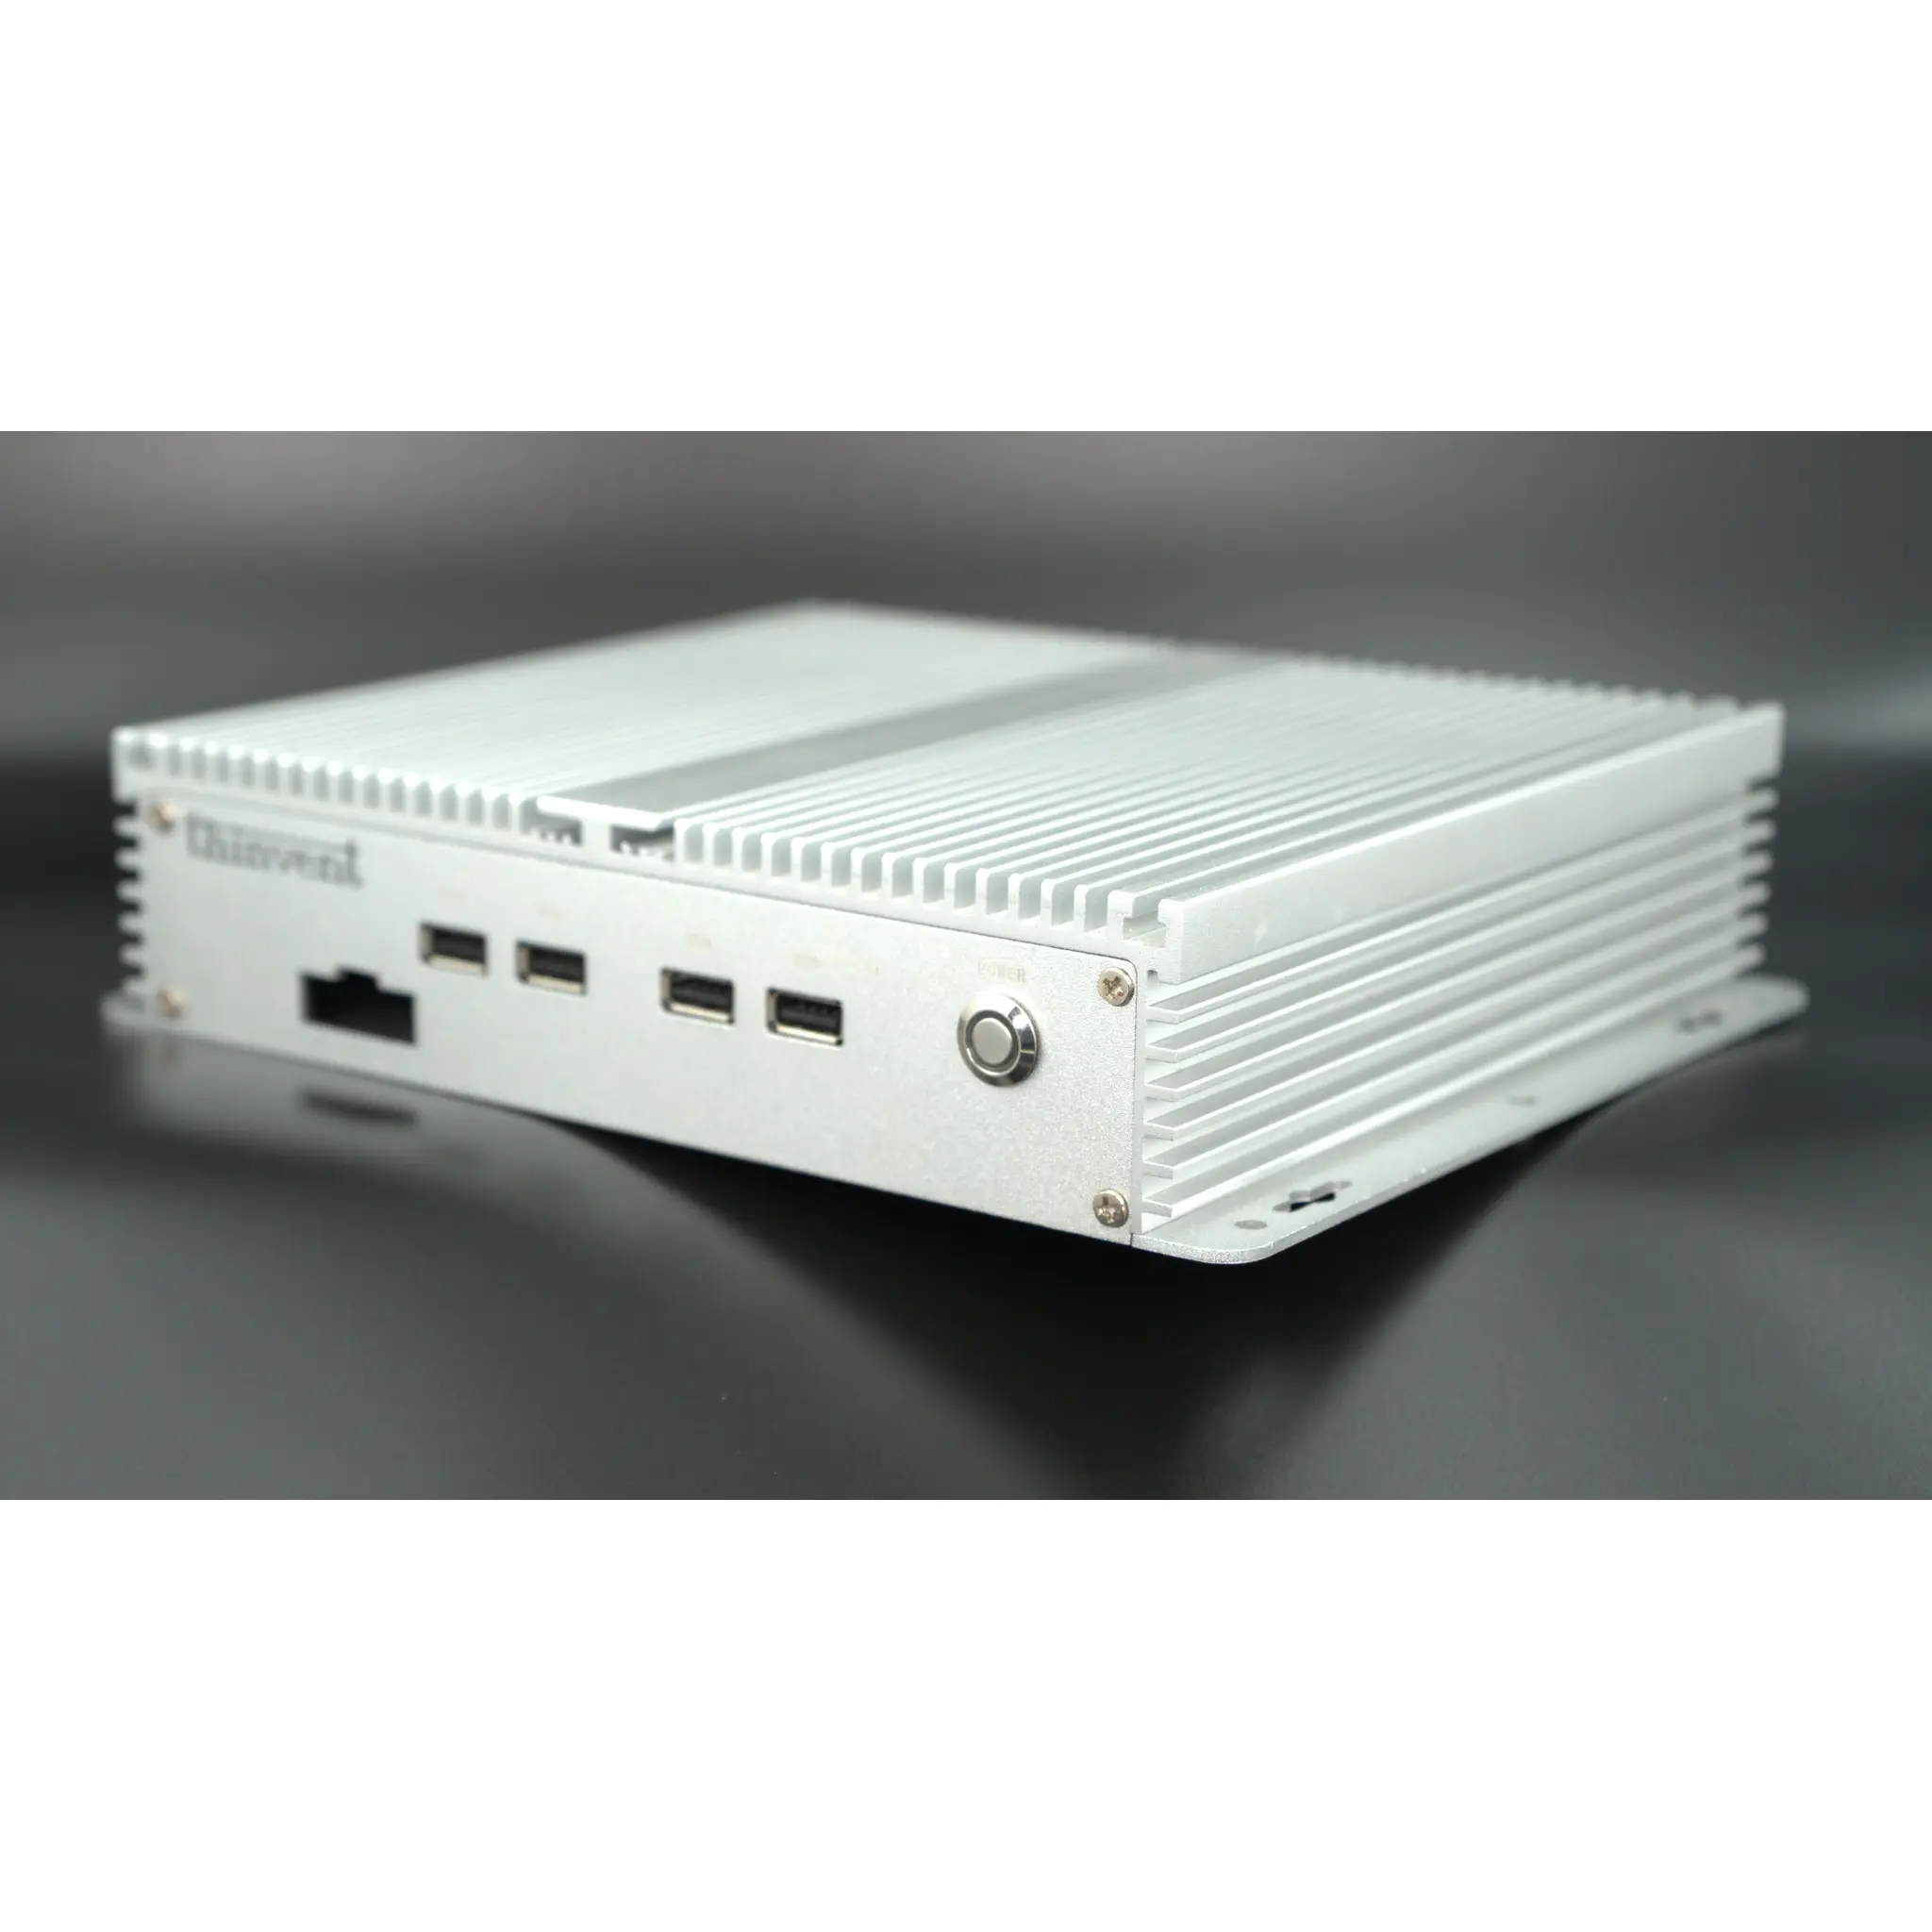
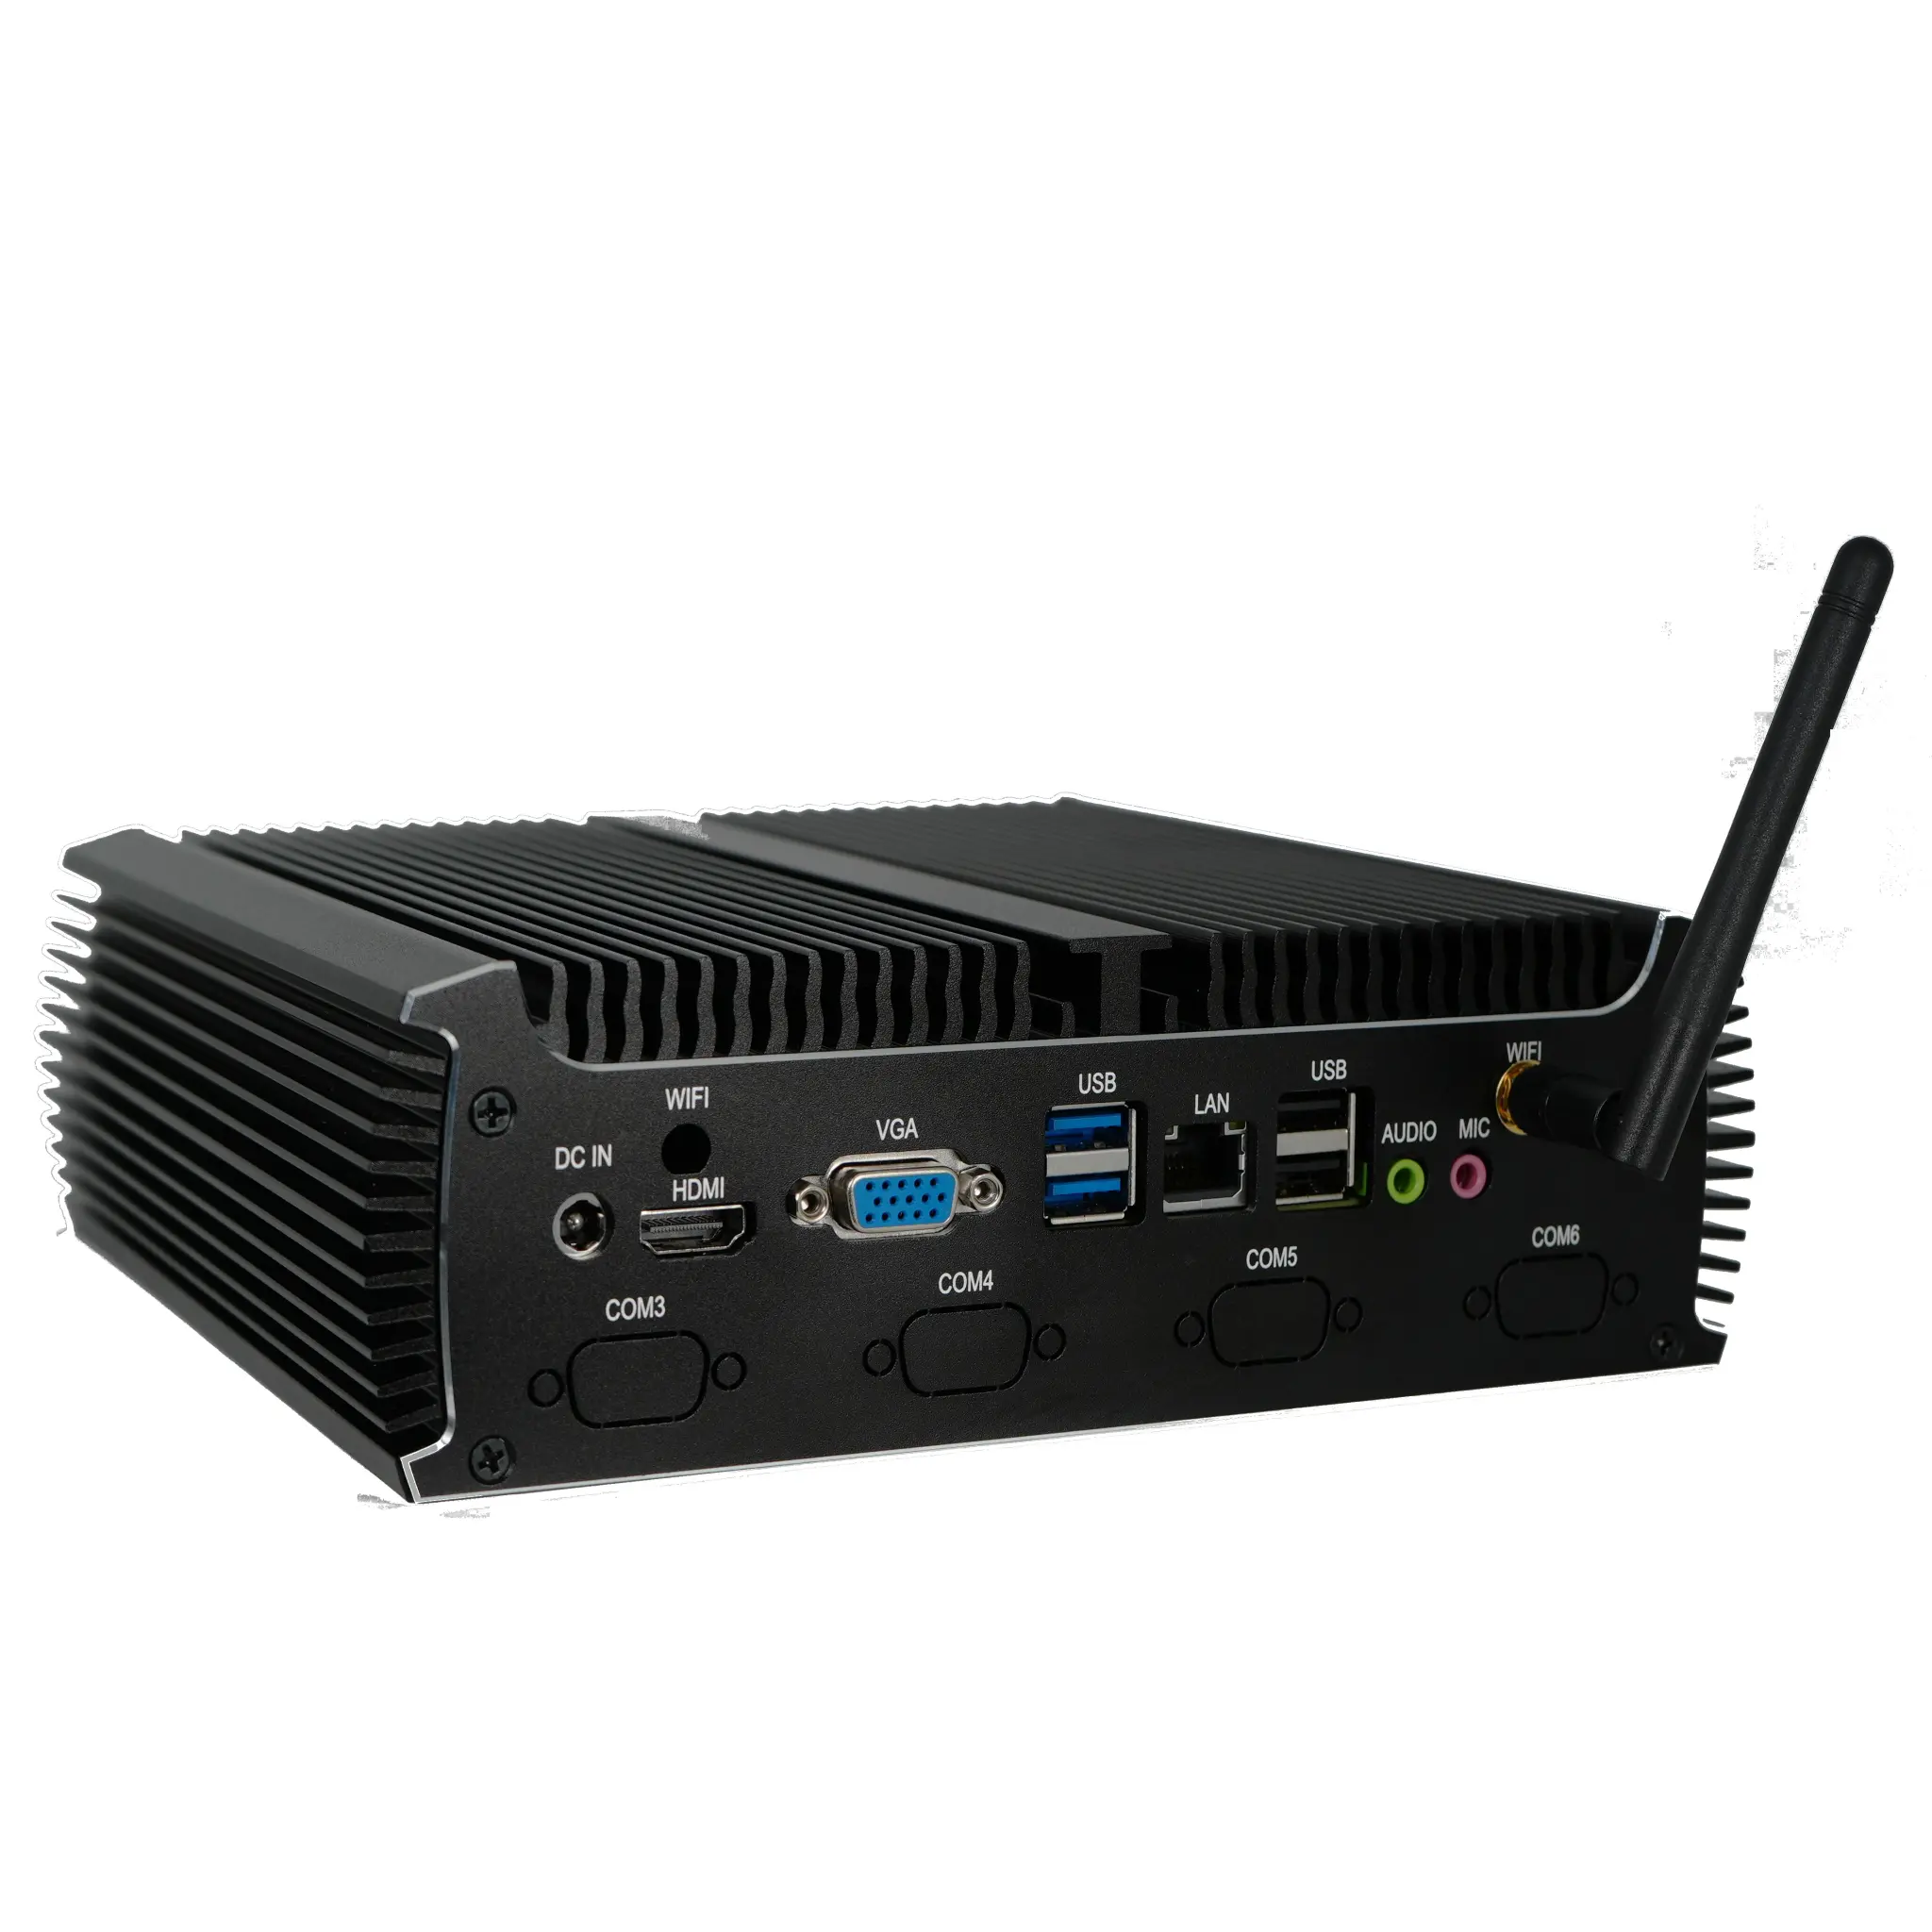
| Thinvent Industrial PC IPC5 | Core i5-1240P (12 cores, 4.4 GHz) | 16GB | 512GB SSD | Small LLMs, multi-tasking |
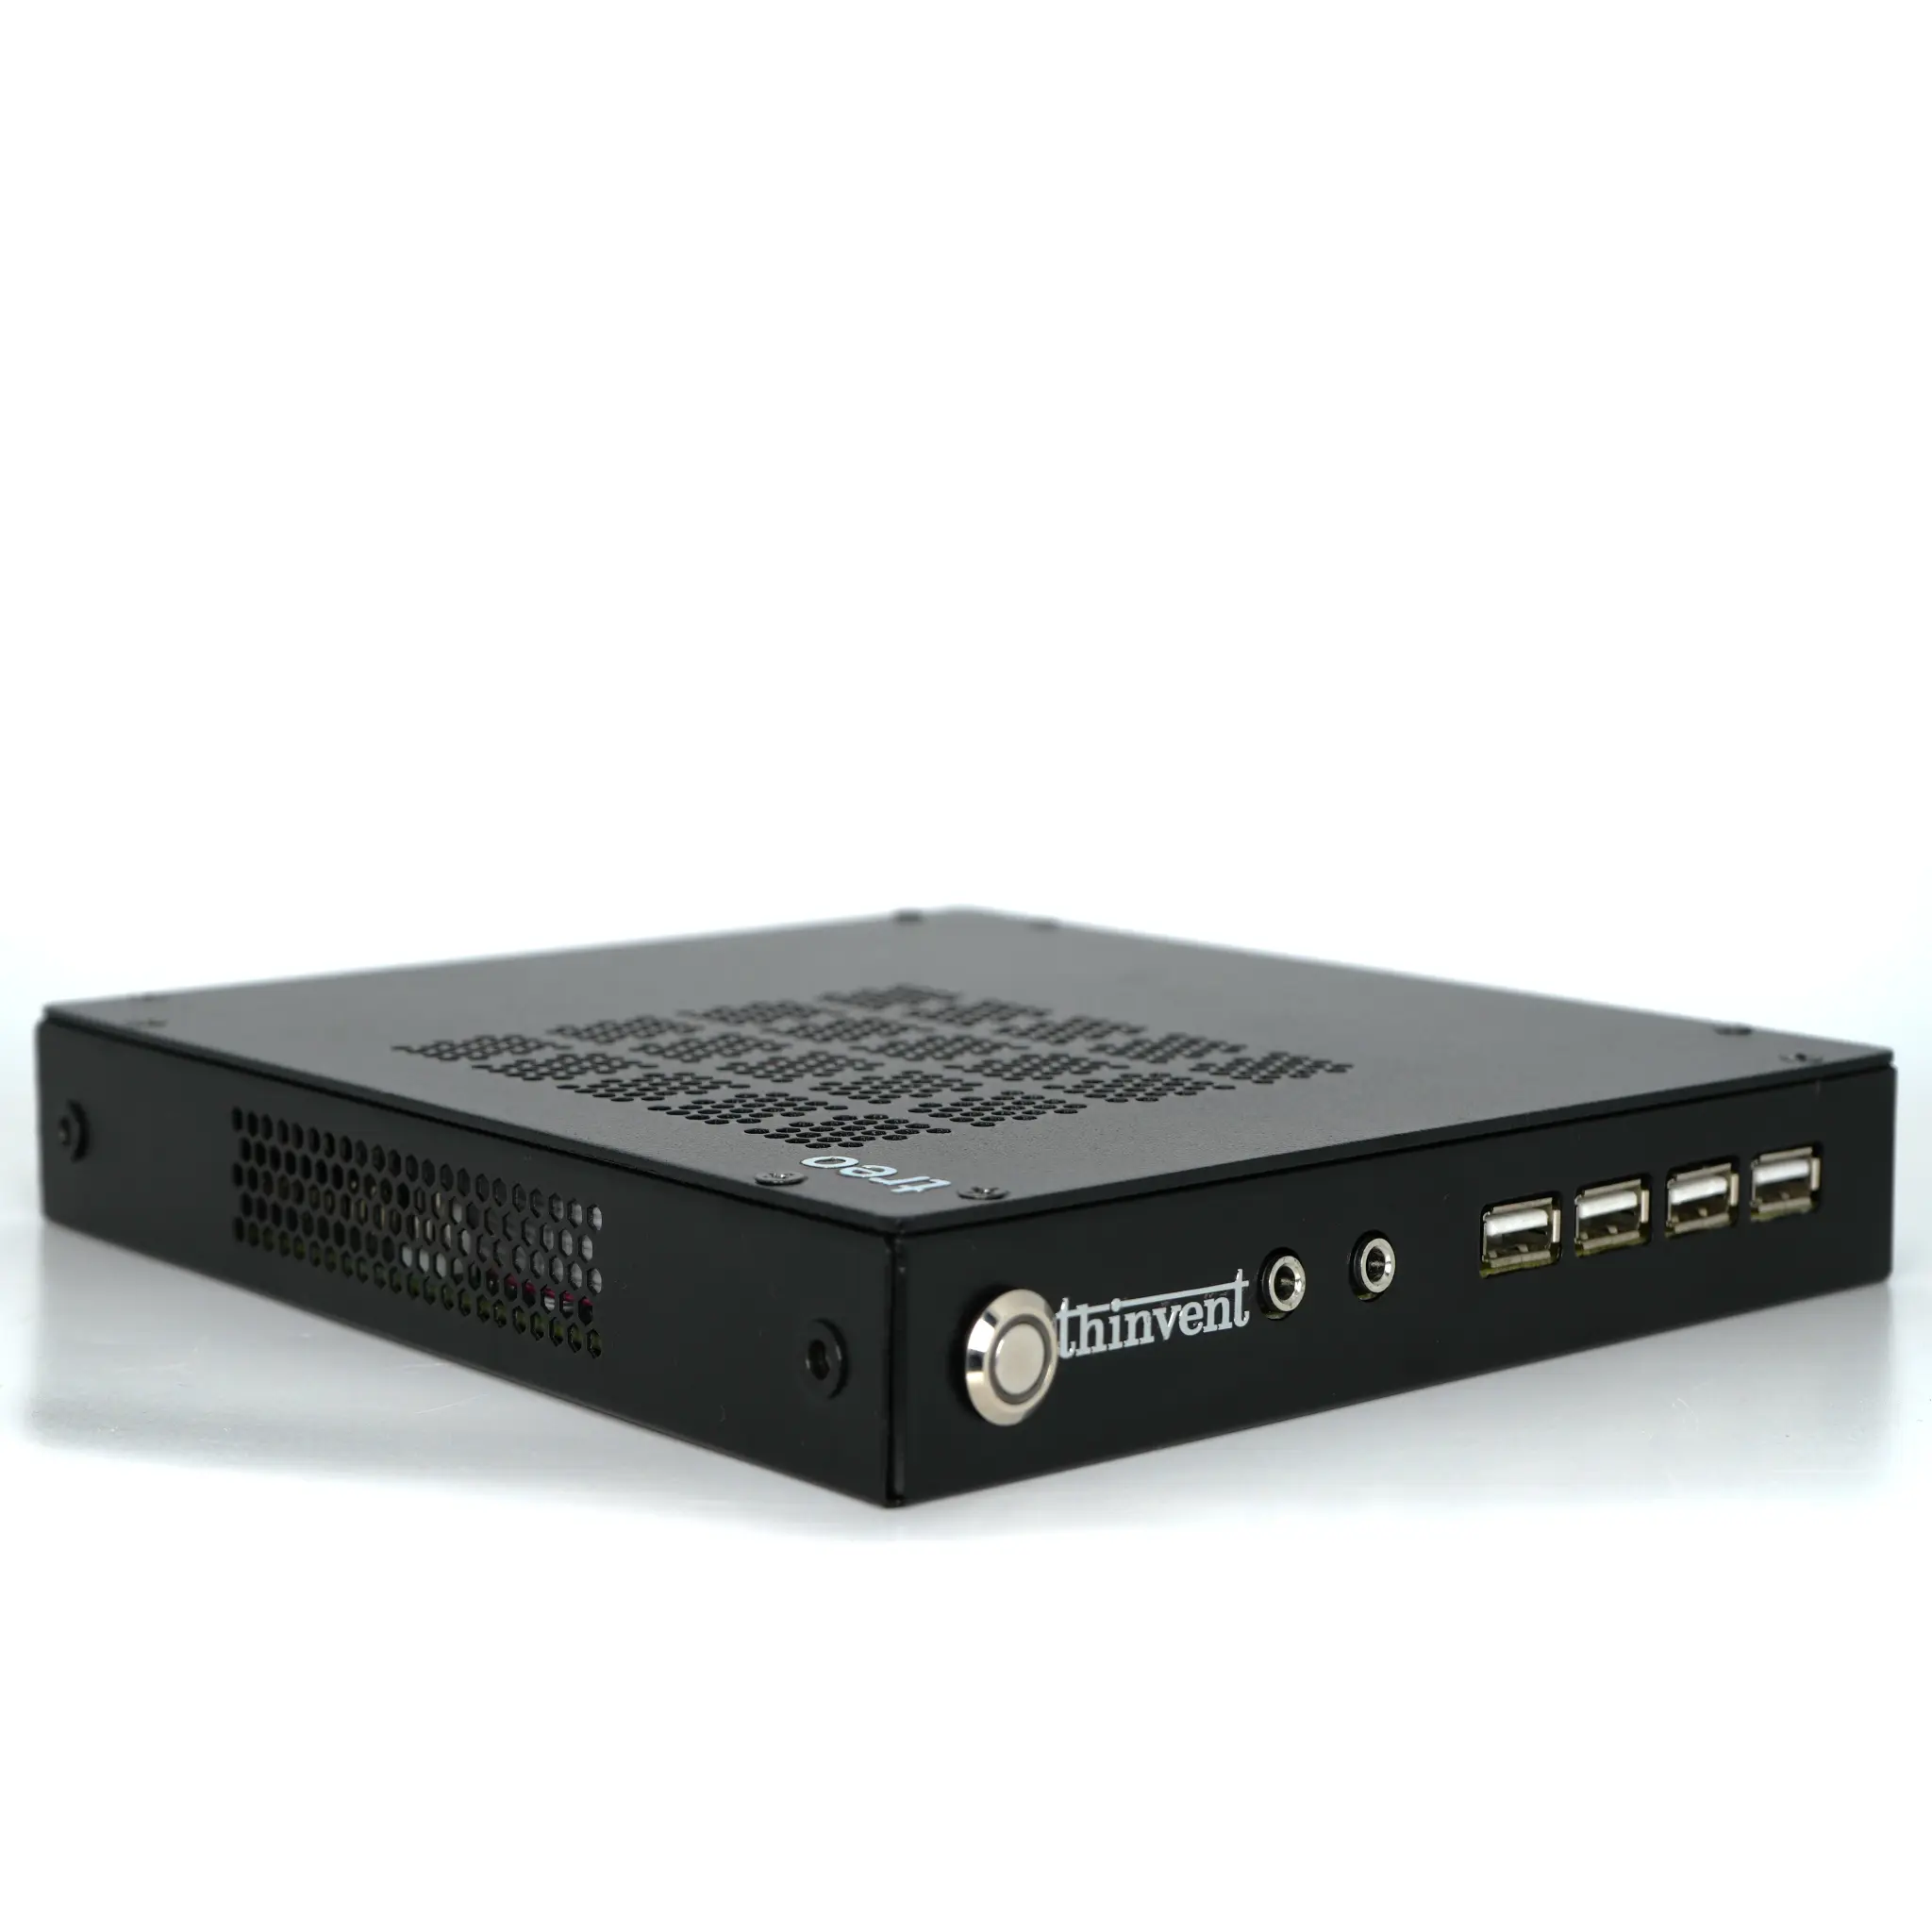
| Thinvent Aero Mini PC (12th Gen) | Core i3-1215U (6 cores, 4.4 GHz) | 8GB | 256GB SSD | Very small quantized models, experimentation |
The Thinvent Aero Mini PC with the 14th Gen Core 5 processor offers the best performance for LLM tasks, with 10 cores, 5.0 GHz boost clock, and 16GB RAM. The IPC5 is also a strong choice for industrial environments requiring rugged reliability.
Applications And Use Cases
Running LLMs locally provides privacy, offline access, and no usage limits. Common use cases include:
-
Personal AI assistants for writing, coding, or research
-
Data analysis with natural language queries on local datasets
-
Content generation for marketing, documentation, or creative work
-
Education and experimentation with machine learning models
For production or heavy workloads, consider systems with upgradeable RAM (32GB+) and add a dedicated GPU via Thunderbolt or PCIe.
Thinvent's Products For LLM Workloads
Thinvent offers a range of Mini PCs and Industrial PCs that can serve as capable platforms for running small to medium LLMs locally. Our Intel-based models with 16GB RAM and fast SSDs provide the necessary foundation for quantized model inference. For users requiring more power, our higher-end models with 10+ core processors and expandability options are ideal. All Thinvent systems are built with industrial-grade reliability, ensuring stable 24/7 operation for AI workloads. Explore our collection to find the right balance of performance, size, and durability for your local LLM needs.