What Makes a PC Good for Running Local LLMs?
Running a Large Language Model (LLM) locally requires a balance of computational power, memory, and storage. Unlike cloud-based inference, local deployment demands hardware capable of handling intensive, sustained workloads. The key specifications to prioritize are CPU performance (high core count and clock speed), sufficient RAM (16GB or more is ideal for many models), and fast storage (SSDs) for loading model weights quickly. While dedicated GPUs offer the best performance, many modern CPUs with integrated graphics and ample system memory can effectively run quantized or smaller LLMs for development, testing, and specific applications.
Key Hardware Specifications for Local LLMs
For successful local LLM deployment, focus on these components:
-
Processor (CPU): A modern multi-core processor is essential. Intel Core i5/i7 series or equivalent, with higher core counts and turbo frequencies (e.g., >3.5 GHz), significantly accelerate model inference and context processing.
-
Memory (RAM): This is often the primary bottleneck. Model size directly correlates with RAM requirements. For running 7B parameter models comfortably, 16GB of RAM is a recommended starting point. Larger models (13B+) may require 32GB or more.
-
Storage: A Solid State Drive (SSD) is non-negotiable. It drastically reduces model load times compared to traditional hard drives. NVMe SSDs offer the best performance.
-
Form Factor & Cooling: Sustained AI workloads generate heat. Industrial and mini PCs with robust, fanless or actively cooled designs ensure stability and reliability during long inference sessions.
Ideal Use Cases and Applications
Deploying LLMs locally is ideal for scenarios requiring data privacy, low-latency responses, or offline operation. Common applications include:
-
Development & Prototyping: Testing and fine-tuning AI models in a controlled, offline environment.
-
Private Data Analysis: Processing sensitive corporate or research data without sending it to the cloud.
-
Edge AI & IoT: Integrating LLM capabilities into kiosks, digital signage, or specialized industrial equipment for intelligent interaction.
-
Cost-Effective Inference: Avoiding recurring cloud API costs for specific, predictable workloads.
Comparing PC Configurations for LLM Workloads
| Use Case / Model Size | Recommended CPU | Minimum RAM | Recommended Storage | Ideal Thinvent Product Line |
|---|---|---|---|---|
| Lightweight / 7B Params (Testing, Small Tasks) | Intel Core i3 / N-series | 8 GB | 256 GB SSD | Treo Series, IPC1 |
| Mainstream / 7B-13B Params (Development, Private Chat) | Intel Core i5 / i7 | 16 GB | 512 GB SSD | Aero Series, IPC3, IPC5 |
| Demanding / 13B+ Params (Research, Data Analysis) | Intel Core i5/i7 (High Core Count) | 32 GB+ | 1 TB+ NVMe SSD | Industrial IPC Series (High-spec configurations) |
Thinvent PCs for Local LLM Deployment
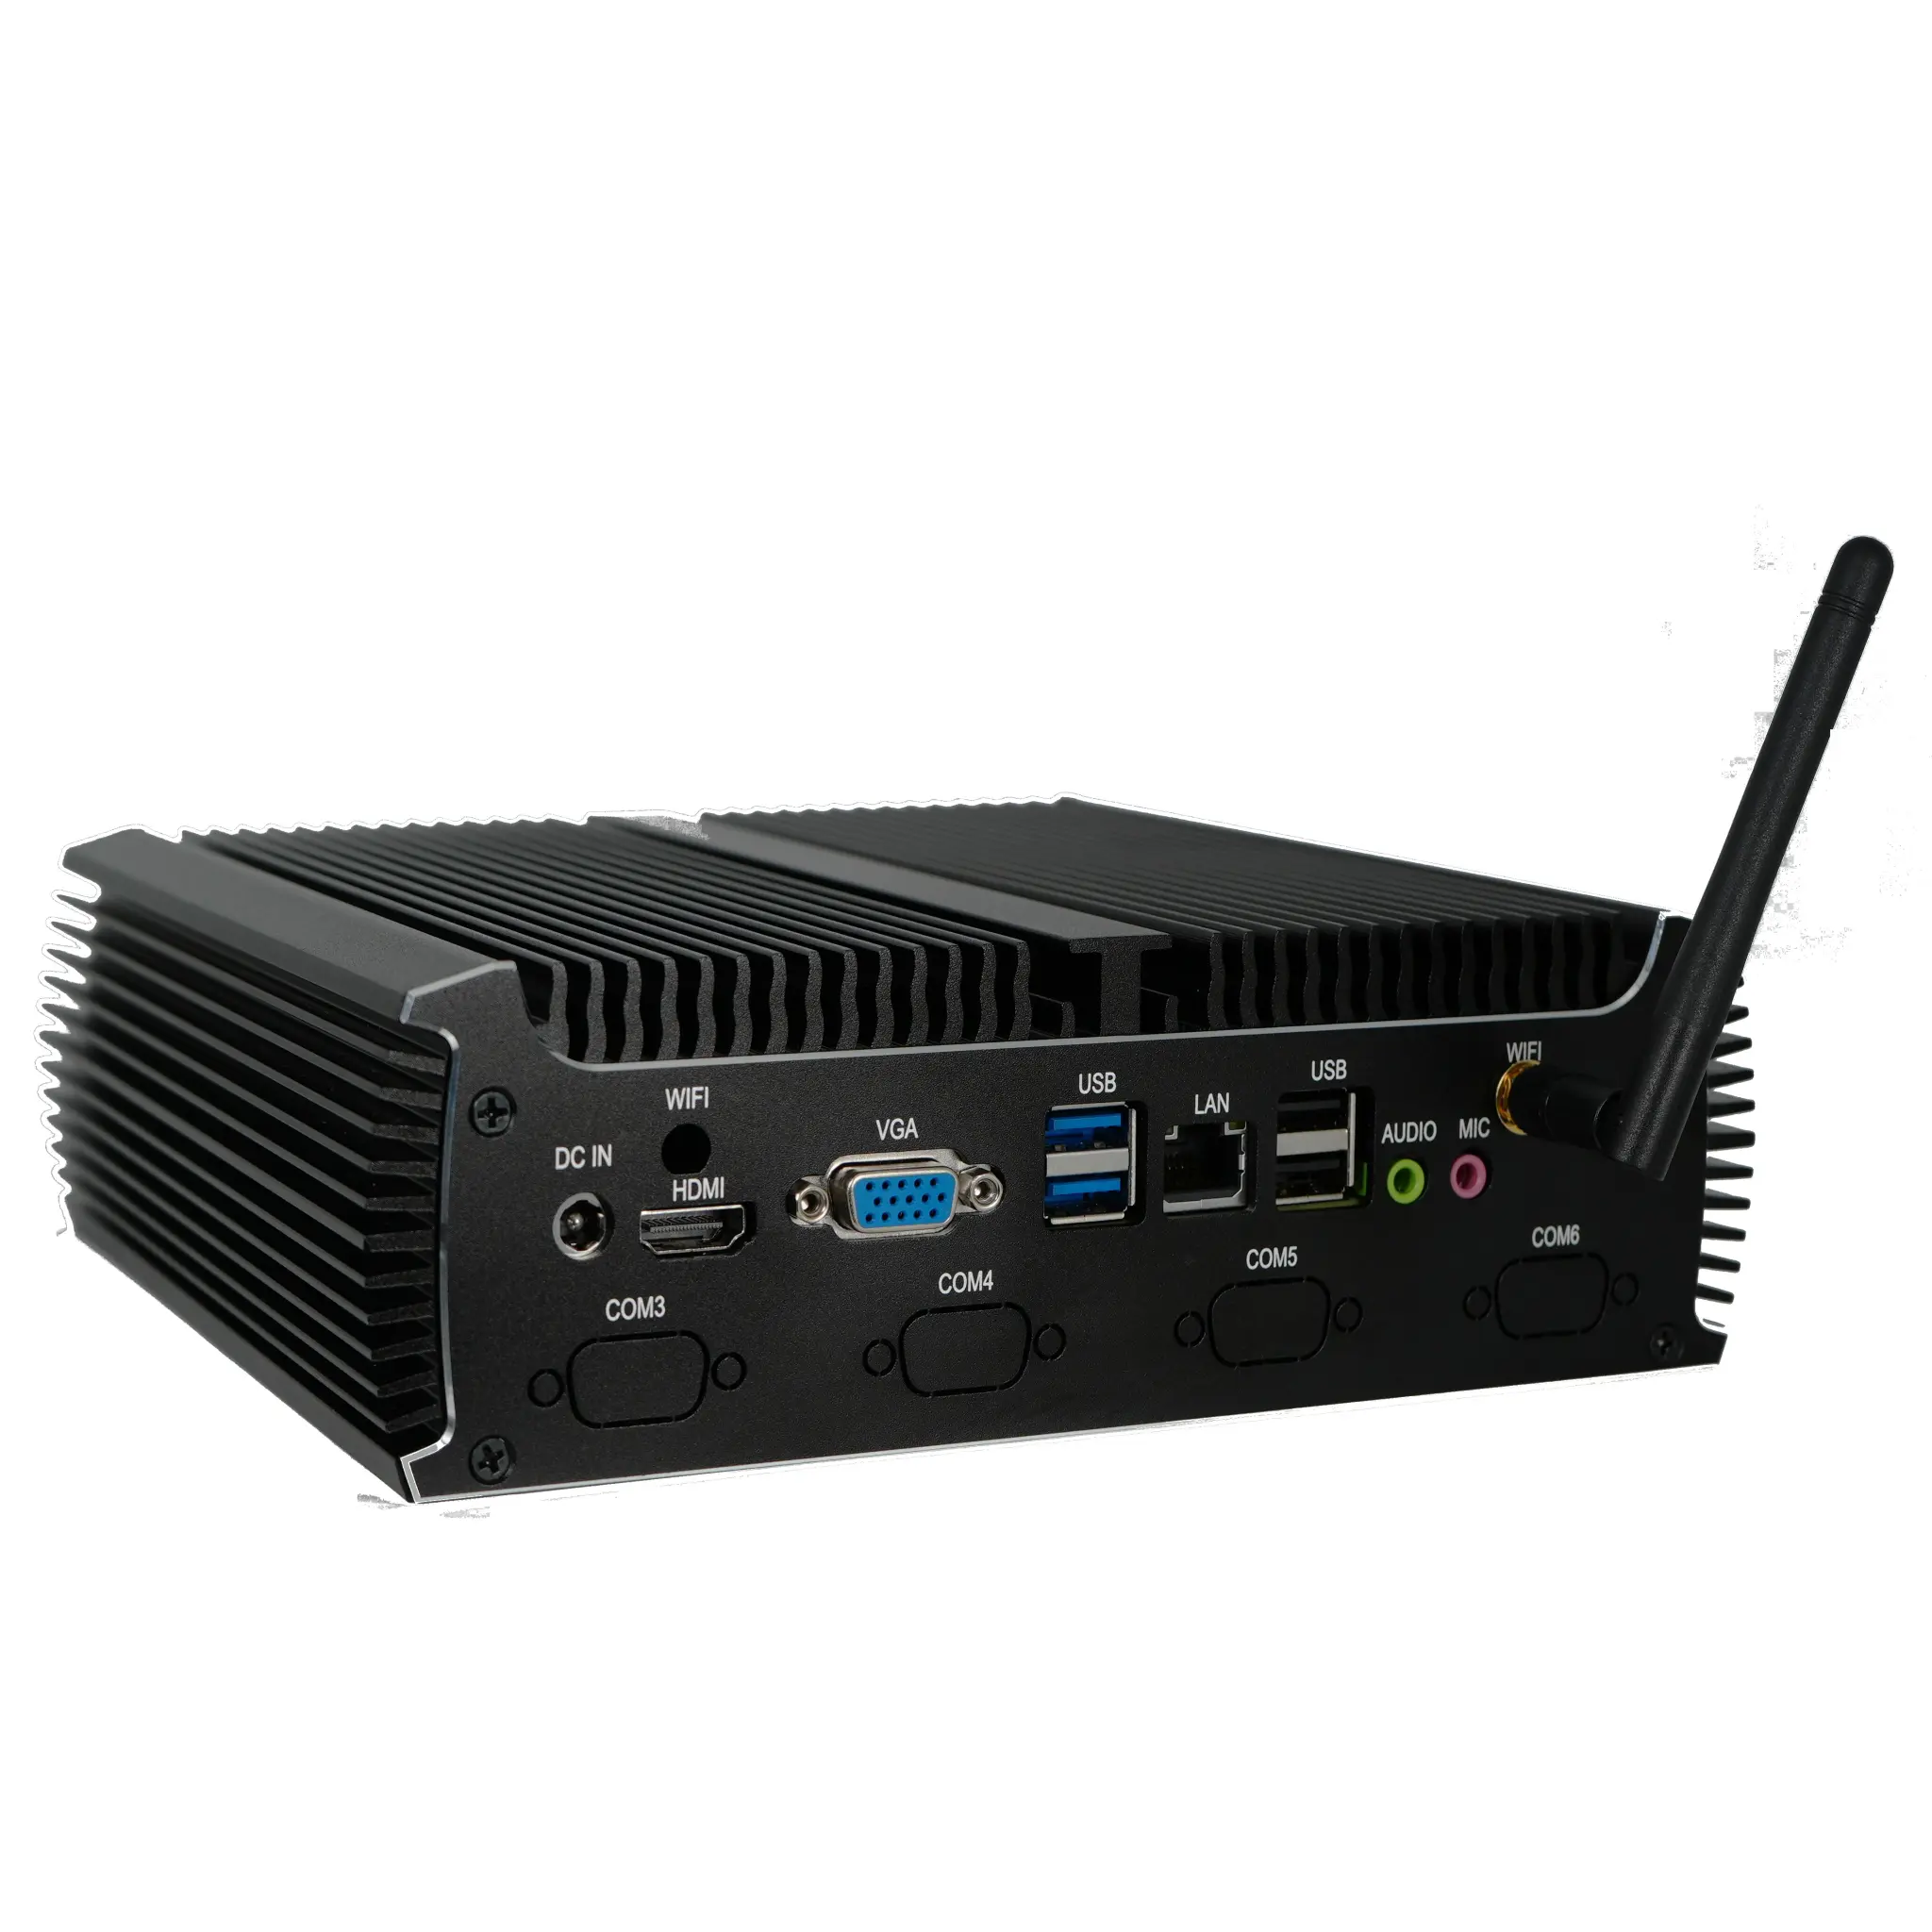
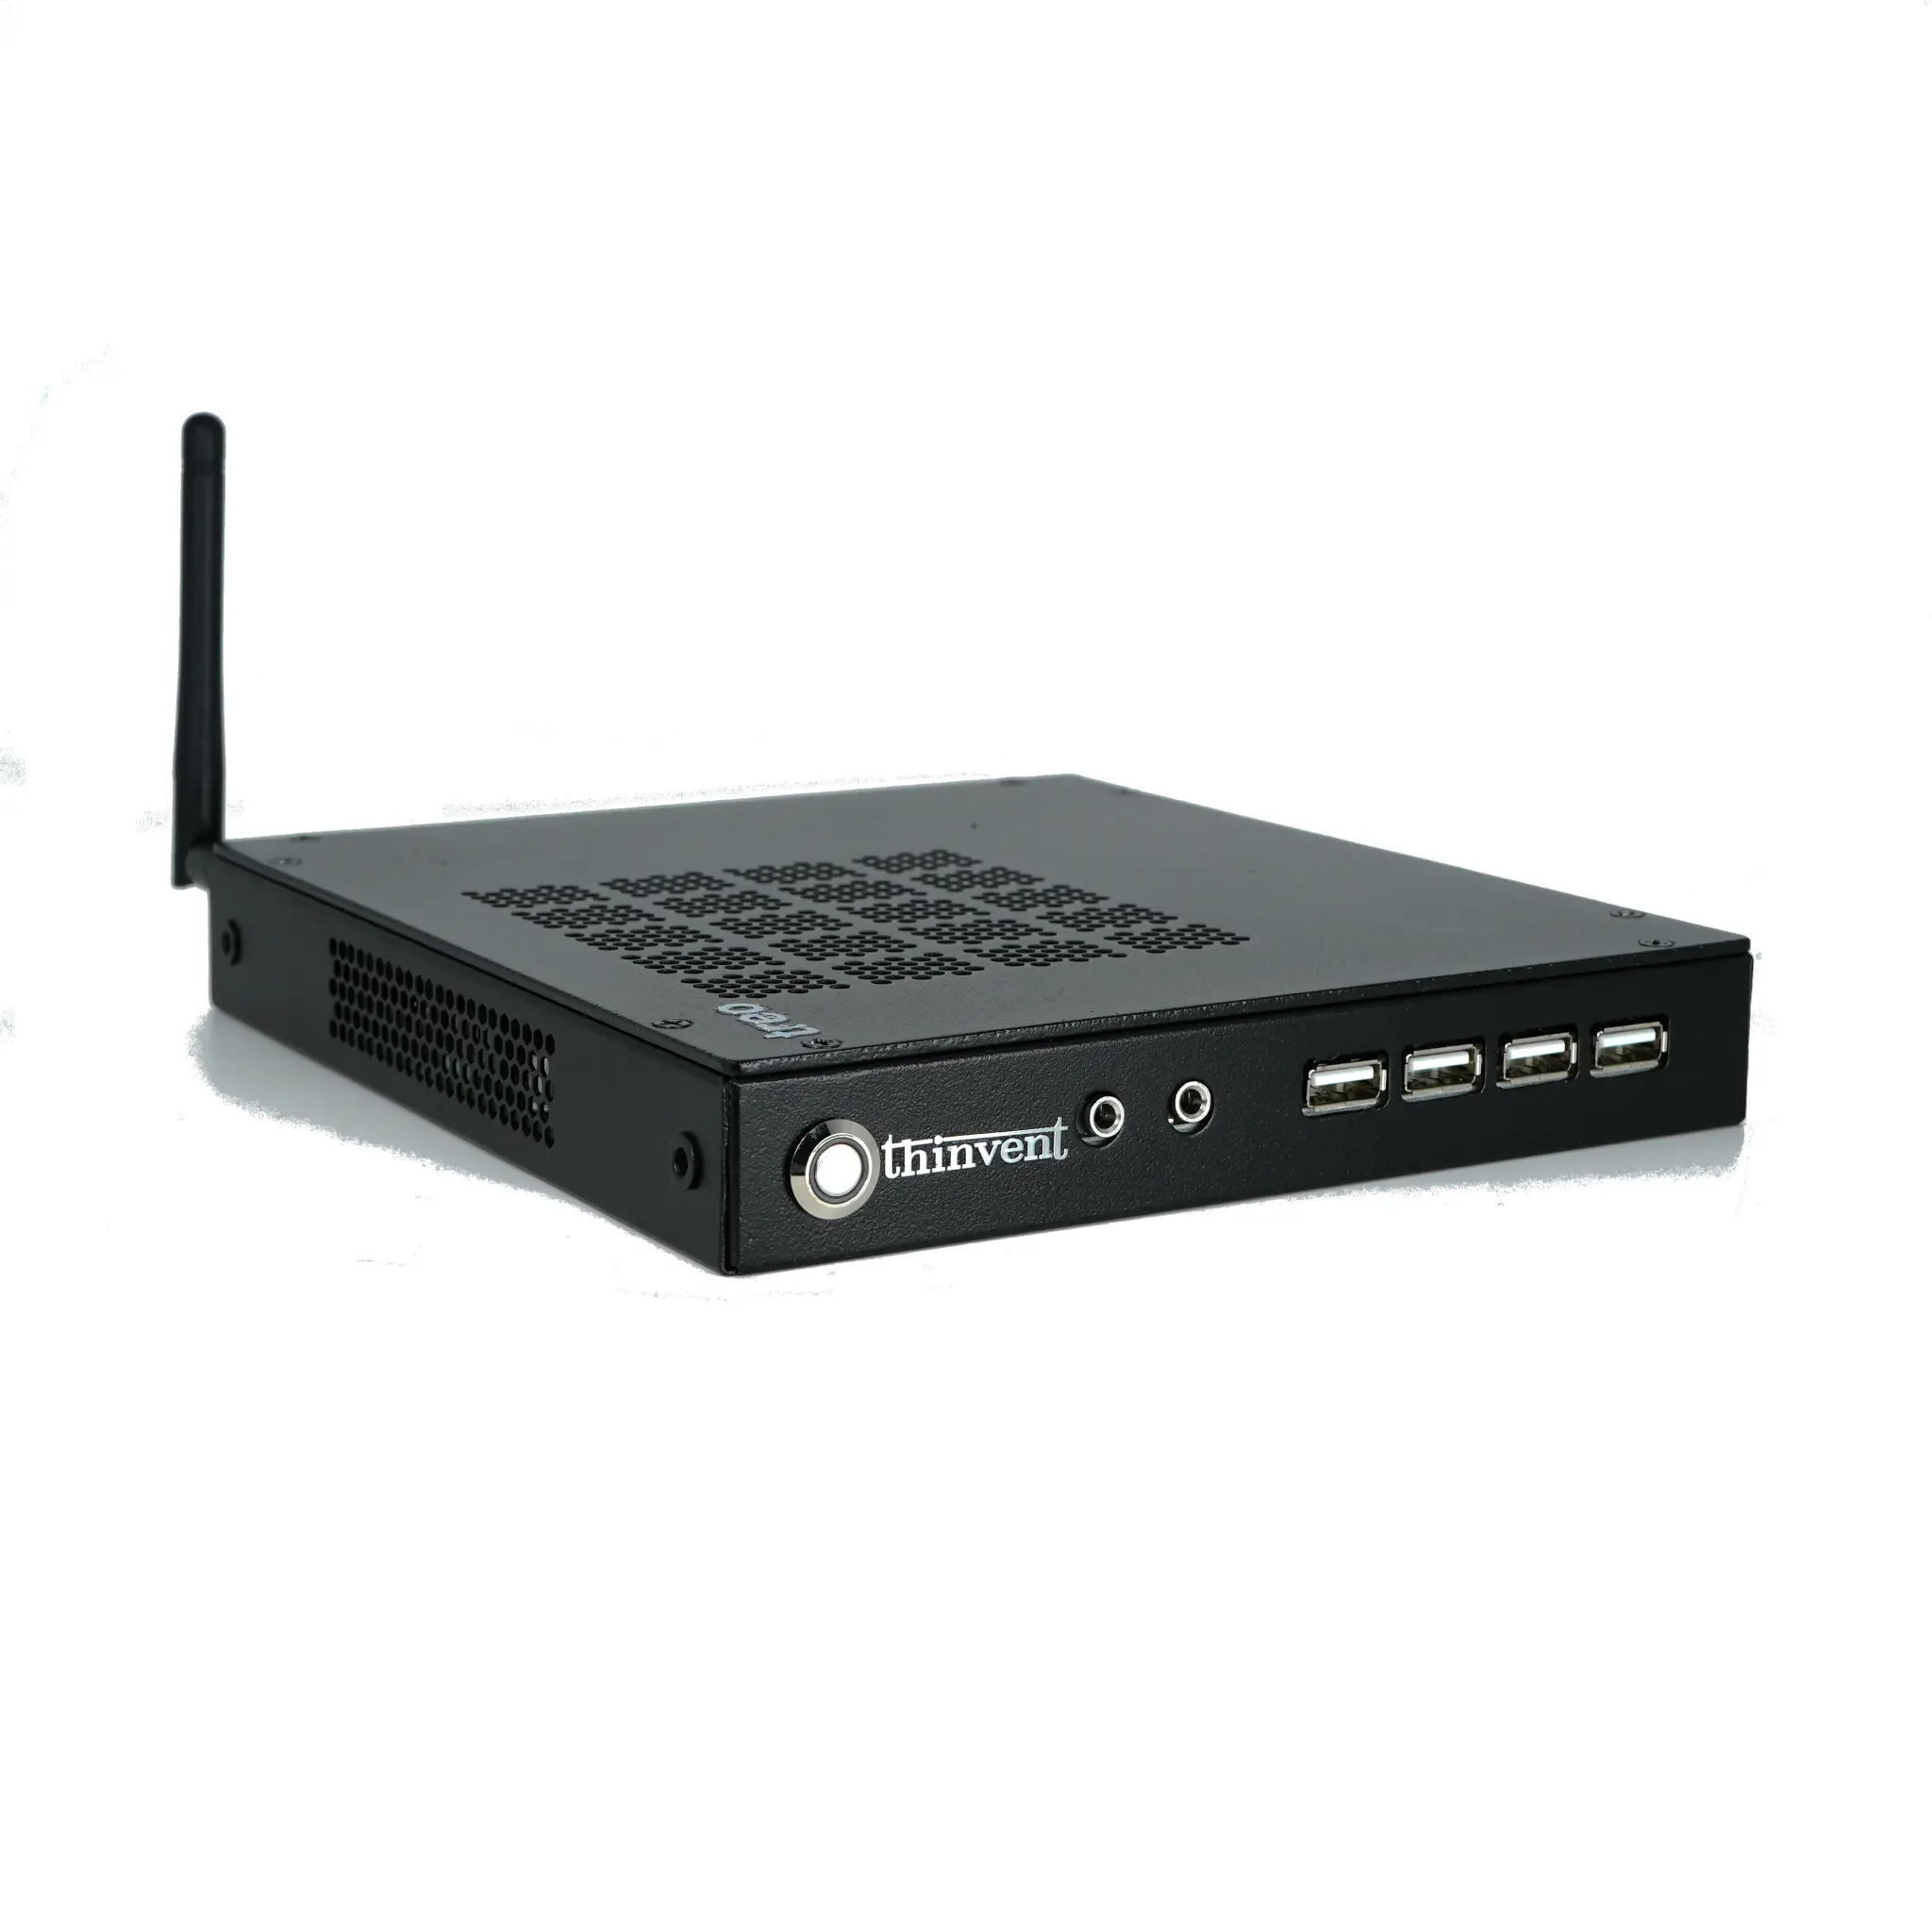
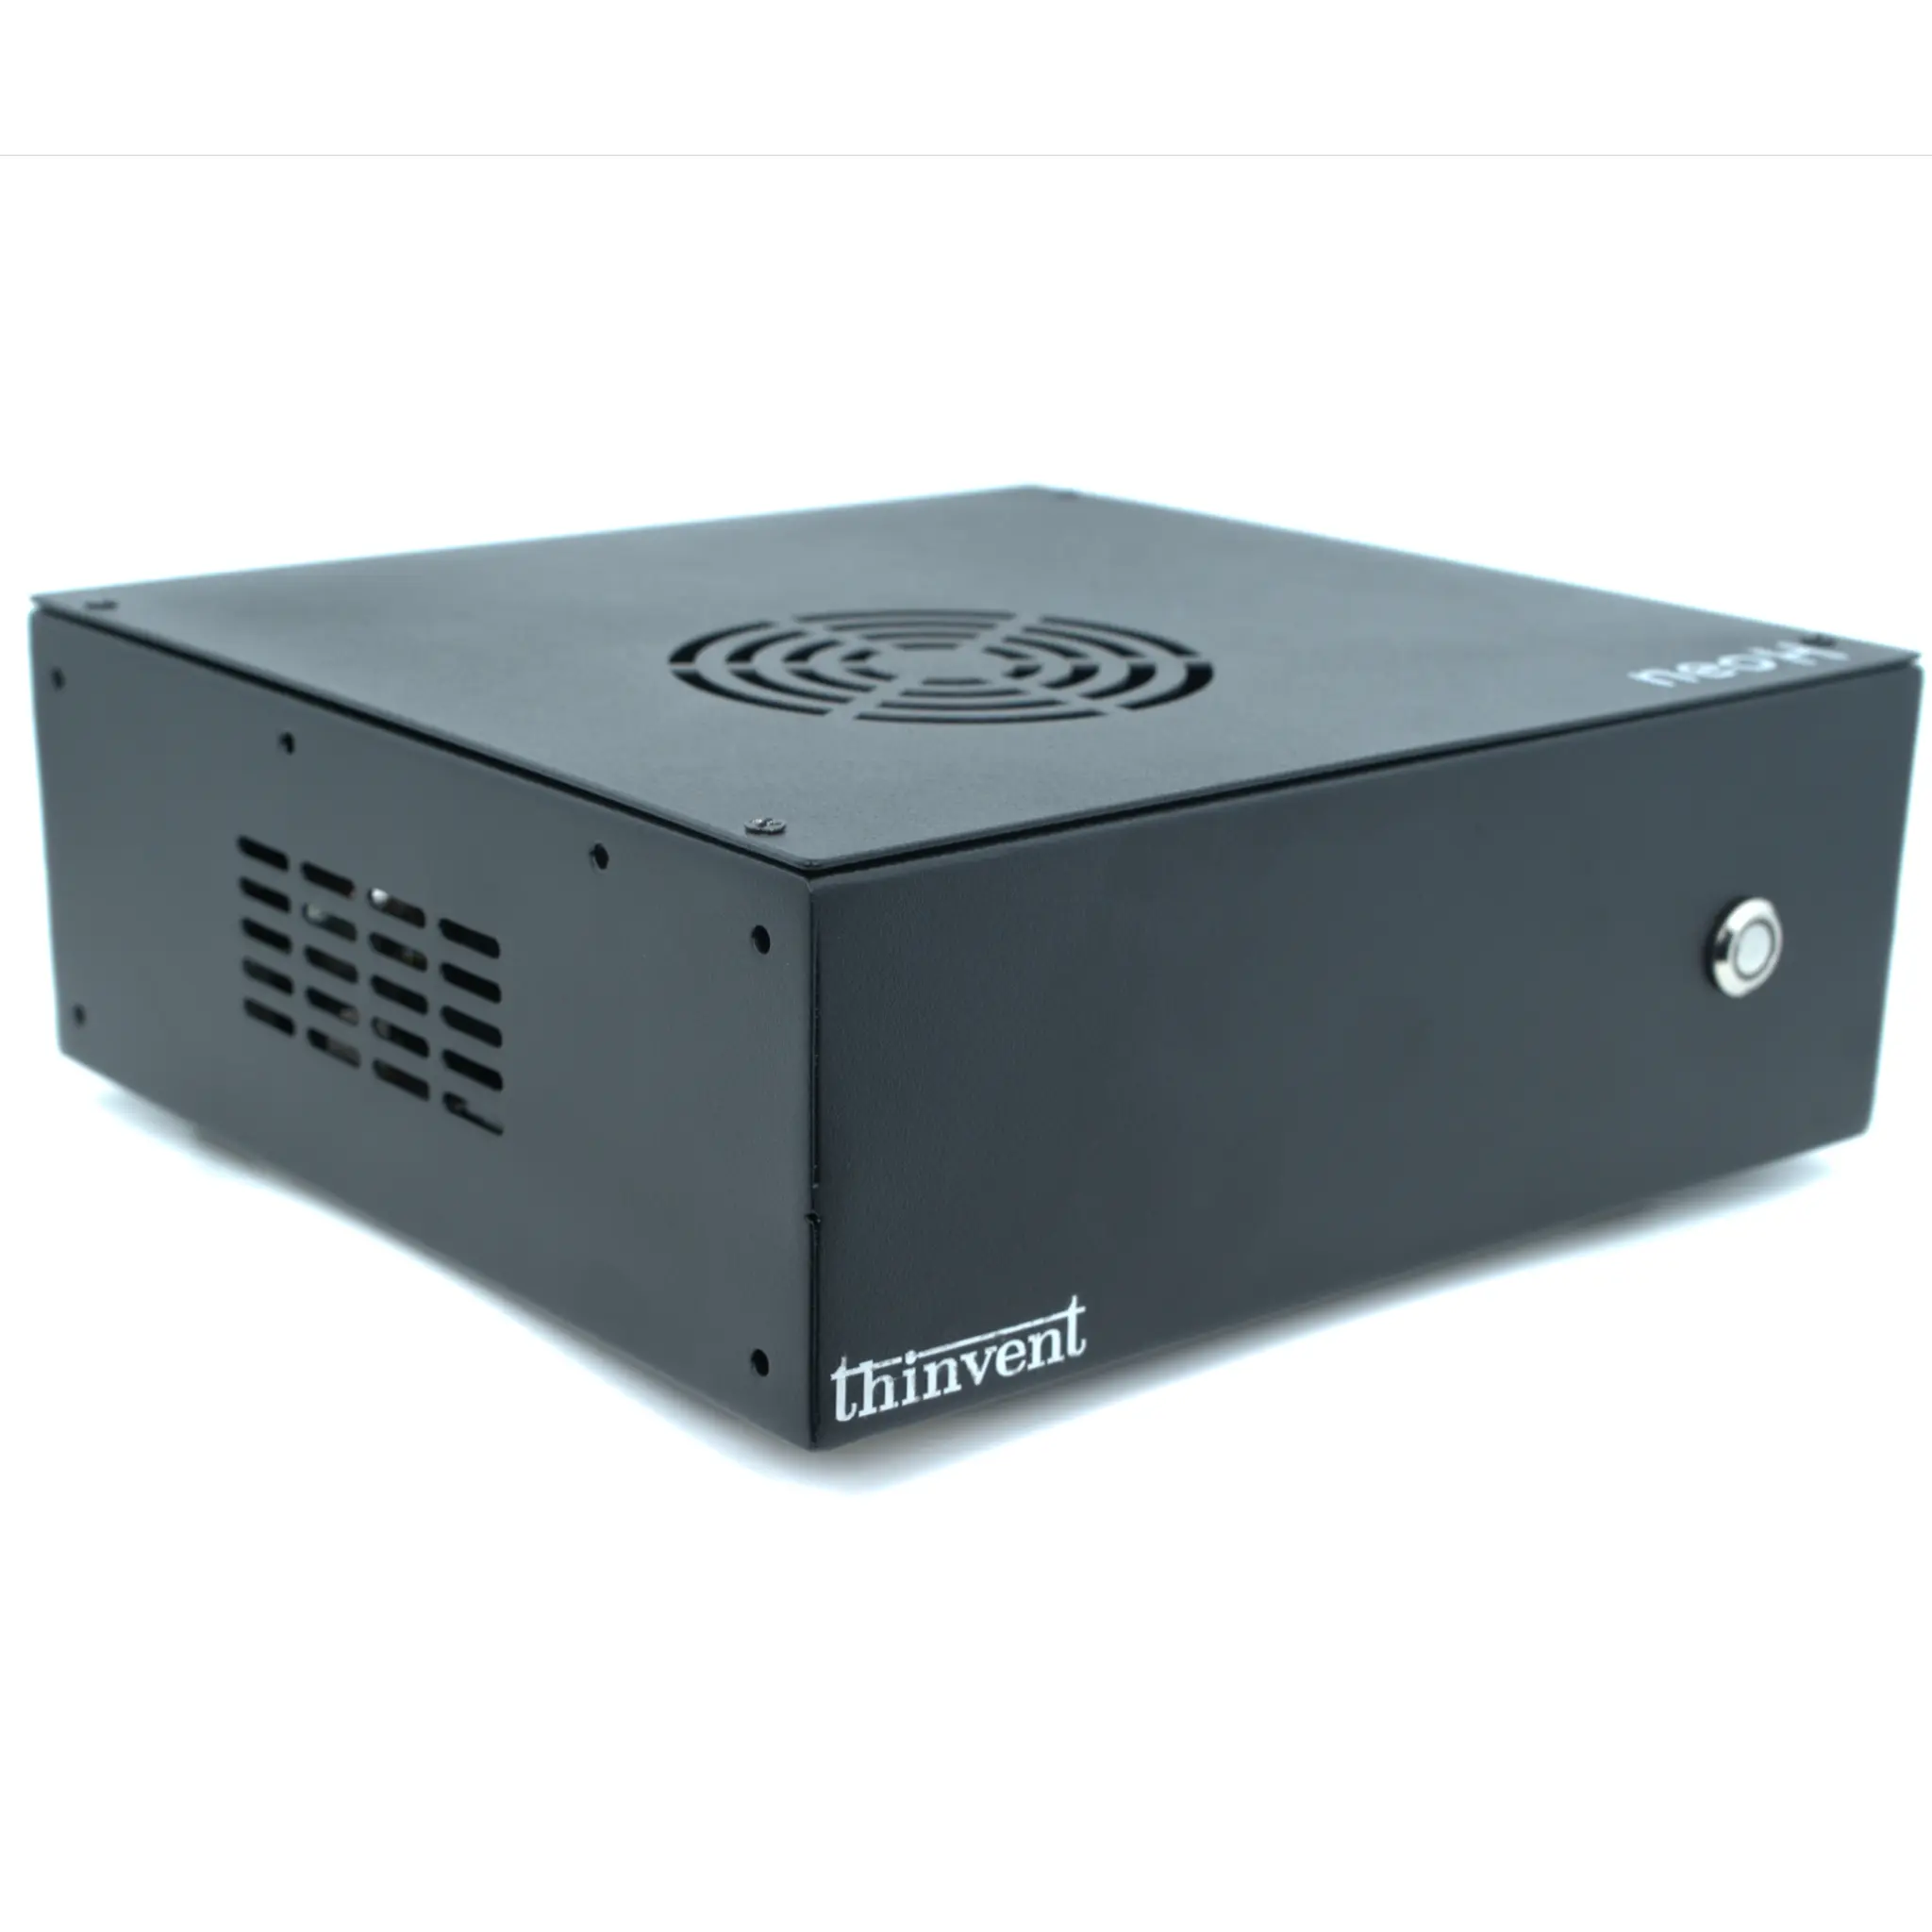
Thinvent offers a range of industrial and mini PCs perfectly suited for deploying local LLMs across different performance requirements. Our Aero Mini PC series, featuring powerful Intel Core i5 processors, up to 16GB RAM, and fast SSDs, provides an excellent balance for mainstream LLM applications. For more demanding, sustained workloads, the Industrial IPC5 with a 12-core Intel i5 processor and 16GB RAM delivers robust performance. For cost-effective testing and lighter models, the Treo Mini PC and IPC1 with the efficient Intel N100 processor offer a capable entry point. All Thinvent systems are built for reliability with efficient cooling solutions, making them dependable partners for continuous AI inference tasks in professional and industrial environments.