What Does "NN" Mean?
In the context of industrial computers, mini PCs and thin clients, NN is the standard abbreviation for "neural network" — an artificial neural network (ANN), the computational model that powers modern machine learning and deep learning. An NN is built from layers of connected nodes ("artificial neurons") that learn patterns from data and then apply those patterns to new inputs. When a model has been trained, the process of running it on live data is called inference, and that is the part of the workflow that hardware at the edge actually performs.
It is worth separating NN from two terms it is often confused with. NPU stands for Neural Processing Unit — a dedicated chip block designed to accelerate neural-network inference, found in newer Intel Core Ultra, AMD Ryzen AI and ARM-based SoCs. NNA (Neural Network Accelerator) is a broader term for any specialised processor optimised for neural-network workloads. So: NN is the model, NPU/NNA is the hardware that speeds it up. "NN" is not a processor series name, a product model number, or a technical standard such as IEC or IP rating.
Why NN Inference Matters on Industrial Hardware
Industrial and embedded deployments rarely train neural networks — training happens on servers or in the cloud. What matters on the factory floor, in a kiosk or at a remote site is deterministic, low-latency inference: reading a camera frame, a sensor stream or a barcode, running it through a trained model, and returning a decision without a round trip to the cloud. That requirement shapes hardware selection, because inference can be executed on three different engines.
| Execution Engine | Typical Hardware | Strengths | Trade-offs |
|---|---|---|---|
| CPU (general purpose) | Intel Celeron, N-series, Core i3/i5 | Runs any framework, no special toolchain, deterministic | Lower throughput for large models |
| Integrated GPU / iGPU | Intel UHD / Iris Xe graphics | Good throughput on vision and matrix maths | Shares memory bandwidth with CPU |
| NPU / dedicated accelerator | Intel Core Ultra, ARM SoCs with NPU | High throughput per watt for INT8/FP16 models | Requires specific runtimes and model conversion |
For most industrial tasks — presence/absence checks, defect classification, OCR, people counting, anomaly detection on vibration or current signals — a modern multi-core x86 CPU with a modest integrated GPU is sufficient, especially when models are quantised to INT8. NPUs become valuable when several camera streams must be processed simultaneously, when power and thermal budgets are tight, or when inference must run with no fans and no cloud dependency at all.
Use Cases Where Neural Network Inference Runs on the Edge
-
Machine vision and quality inspection — classifying weld seams, PCB solder joints, printed labels or fabric defects directly on the line, without shipping images off-site.
-
Access control and people counting — face or person detection on a local mini PC, keeping biometric data inside the facility for privacy and compliance.
-
Predictive maintenance — running small models over vibration, temperature and current telemetry to flag bearing wear before a stoppage.
-
Retail and kiosk analytics — queue length, dwell time and shelf-engagement measurement on an all-in-one or thin-client-driven display.
-
Logistics and OCR — reading number plates, parcel labels and pallet IDs at dock doors, often in unheated or dusty environments.
Matching NN Workloads to the Right Form Factor
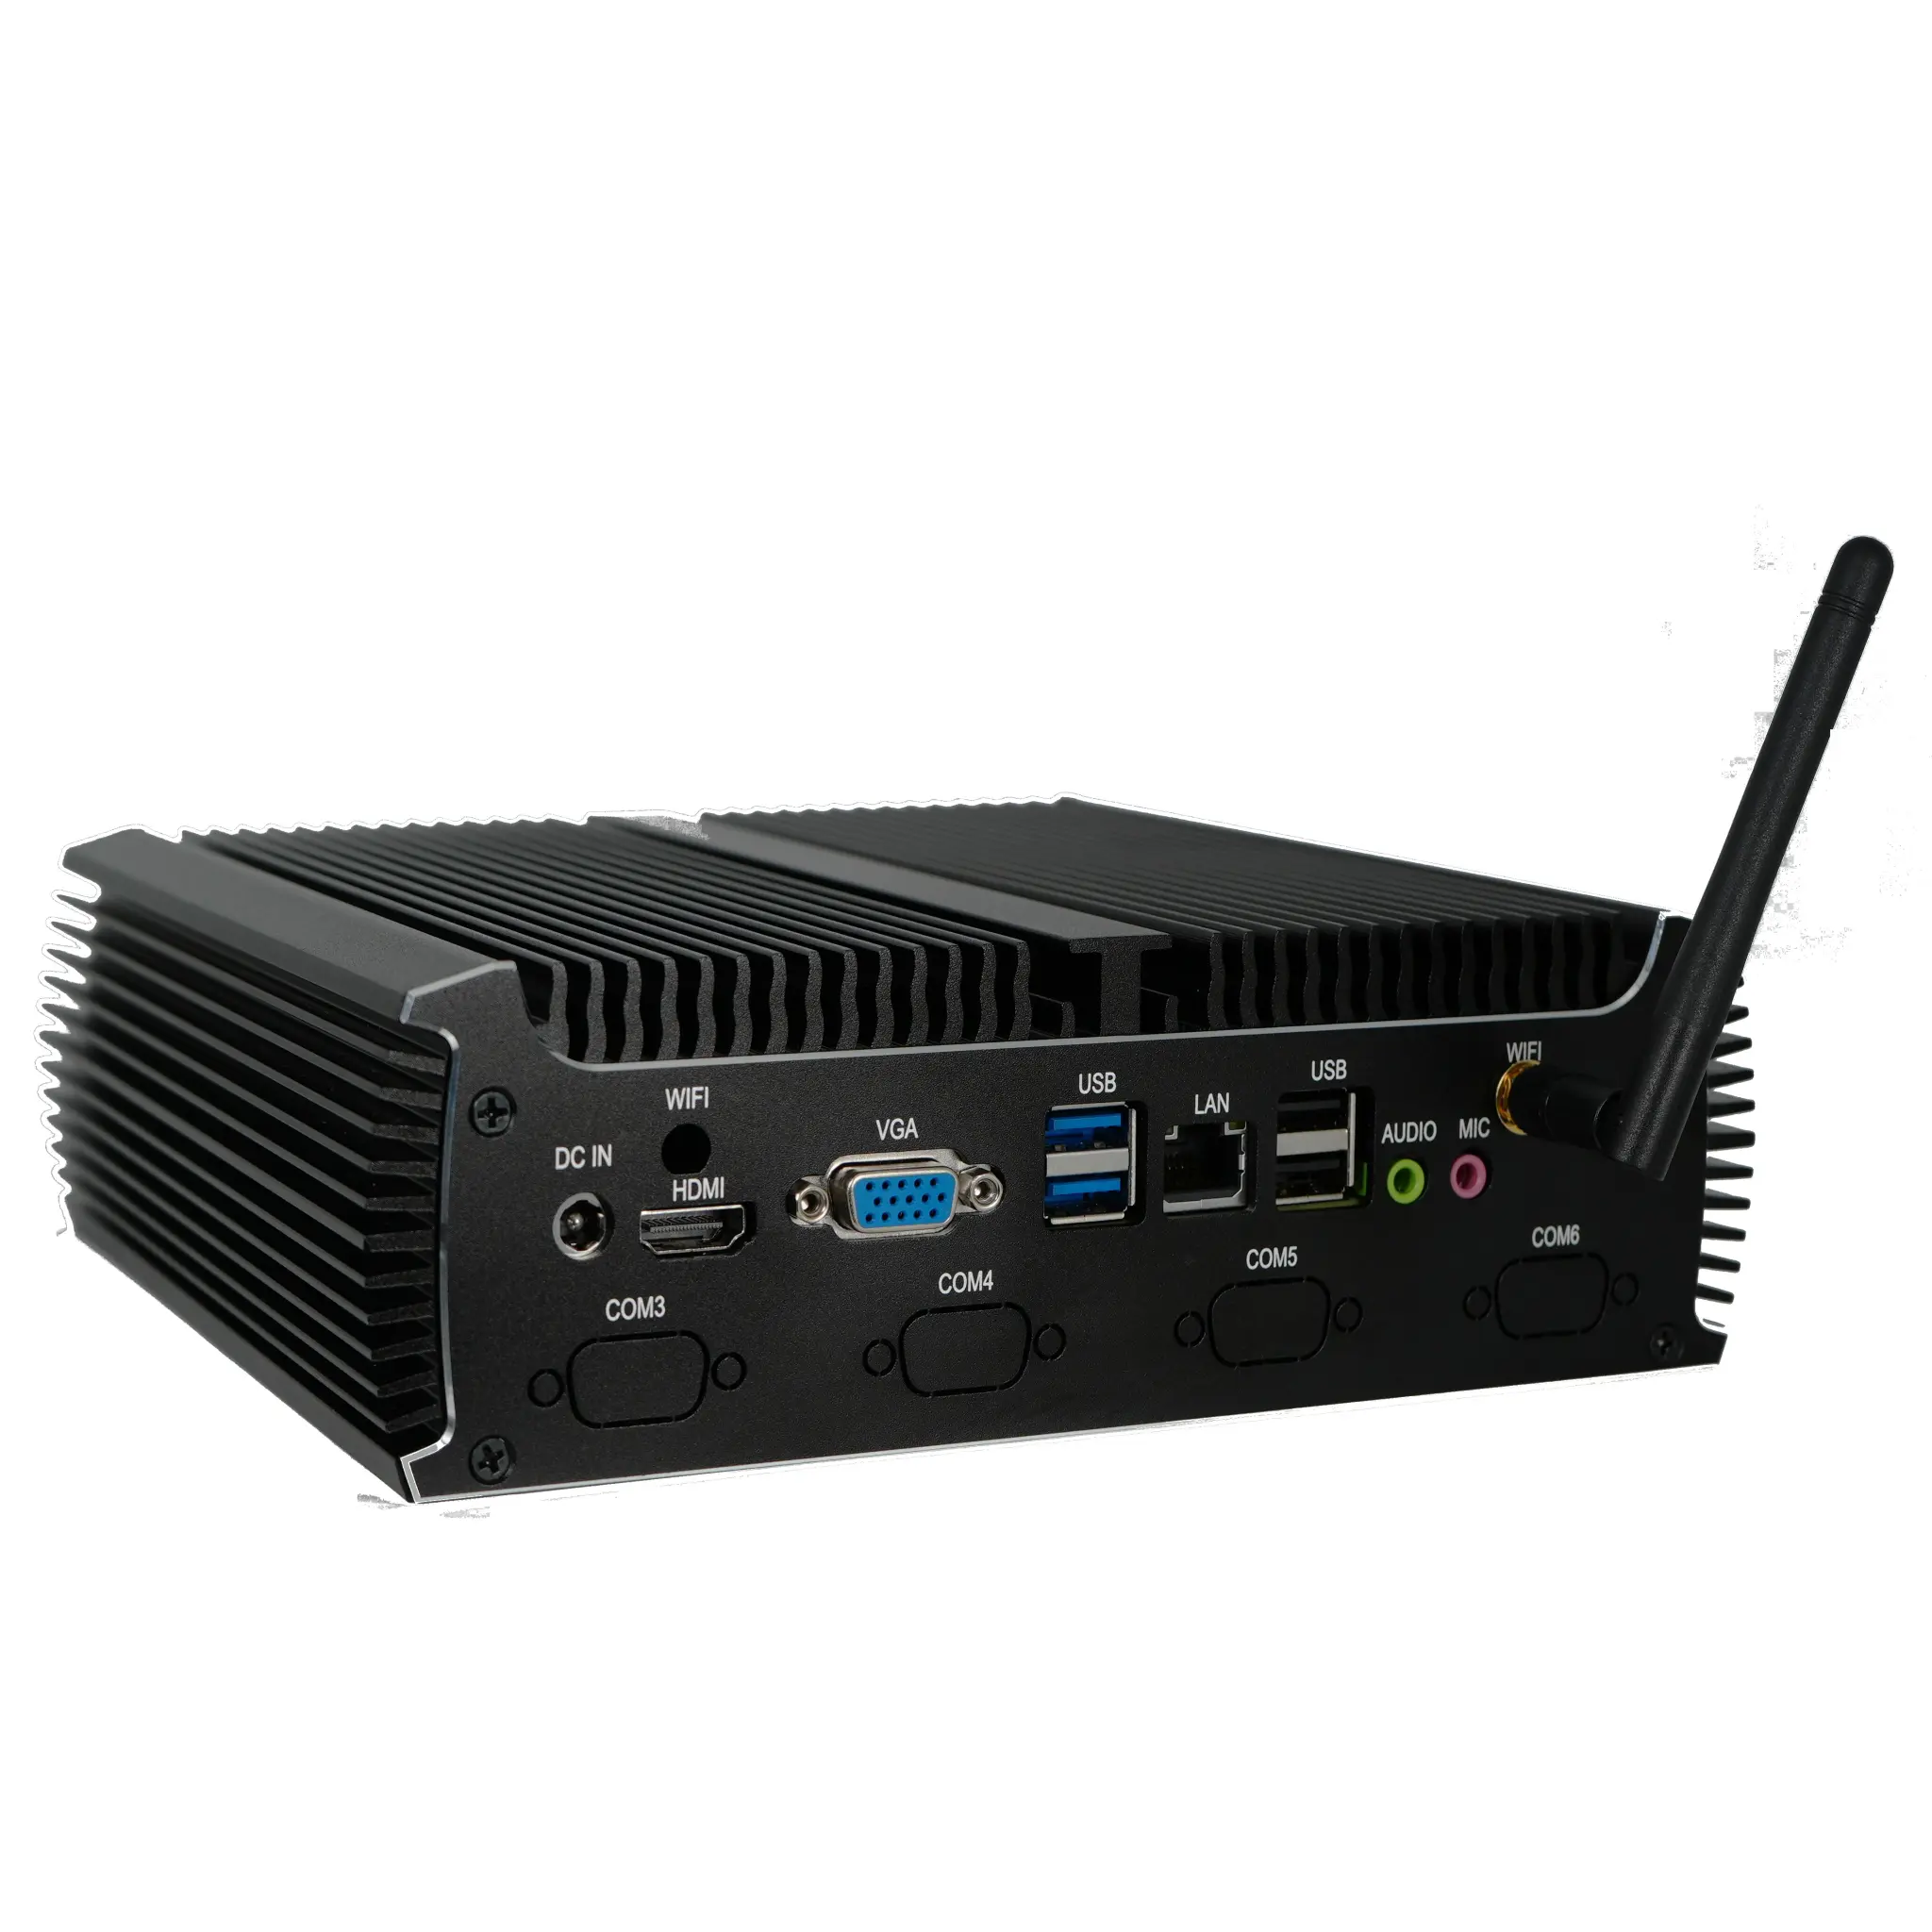
The physical format usually follows from the environment rather than the model. A fanless industrial PC is the default choice where dust, heat, vibration or 24/7 duty cycles rule out consumer hardware and moving fans. A mini PC suits office-adjacent or cabinet