What Does "Open Source AI Model" Mean for Hardware?
An open source AI model is a machine learning model whose weights, architecture and often training code are released under a licence that lets anyone study, modify and redistribute them. Well-known examples include the Llama family, Mistral, Gemma, Phi, Qwen and Stable Diffusion, alongside thousands of models published on repositories such as Hugging Face. Because these models are free to download and self-host, the hardware question shifts from "which cloud subscription?" to "which computer can run inference locally, reliably and affordably?"
What Hardware Do Open Source AI Models Need?
The answer depends heavily on model size and quantisation. Small language models (0.5B–3B parameters) and classic vision/ML models run comfortably on a modern multi-core x86 CPU with 8–16 GB of RAM, especially when weights are quantised to INT8 or INT4. Mid-sized models (7B–8B) benefit from 16–32 GB of RAM and run acceptably on CPU with libraries such as llama.cpp, ONNX Runtime or OpenVINO, while larger models generally want a discrete GPU or NPU accelerator. Storage matters too: a quantised 7B model occupies roughly 4–8 GB on disk, so a 512 GB or 1 TB SSD leaves ample room for several models plus the application stack.
| Model Class | Typical Parameters | Practical RAM | Storage per Model | CPU Feasibility |
|---|---|---|---|---|
| Tiny / edge | 0.5B–3B | 8 GB | 1–3 GB | Excellent |
| Small LLM | 7B–8B (INT4) | 16 GB | 4–8 GB | Good |
| Mid LLM | 13B–14B (INT4) | 32 GB | 8–12 GB | Workable |
| Large LLM | 30B+ | 64 GB+ | 20 GB+ | GPU recommended |
| Vision / ML | CNN, detection | 8–16 GB | < 2 GB | Excellent |
Where Local AI Inference Makes Sense
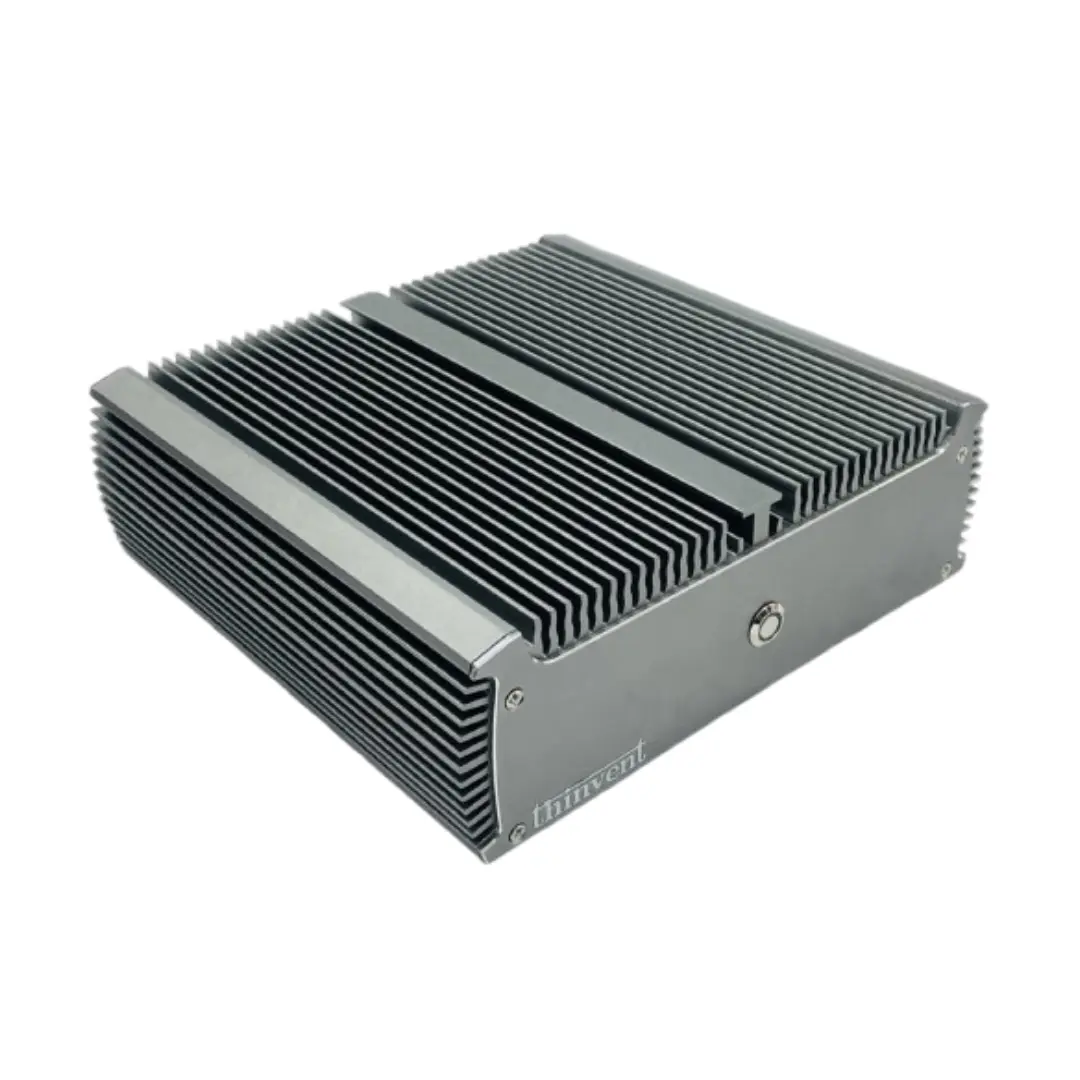
Running open source models on local hardware keeps sensitive data on-premises, removes per-token API costs and works without an internet connection — all critical in factories, hospitals, retail back offices and remote sites. Typical deployments include OCR and document extraction, defect detection on production lines, natural language search over internal records, voice transcription, chatbots for kiosks and predictive maintenance on time-series sensor data. An industrial computer with a 6-core Intel® Core™ processor, 16 GB of DDR4 RAM and a 1 TB SSD comfortably hosts a quantised small language model alongside the application that consumes it, and fanless chassis designs avoid drawing dust into the enclosure on a shop floor.
Choosing an Operating System and Runtime
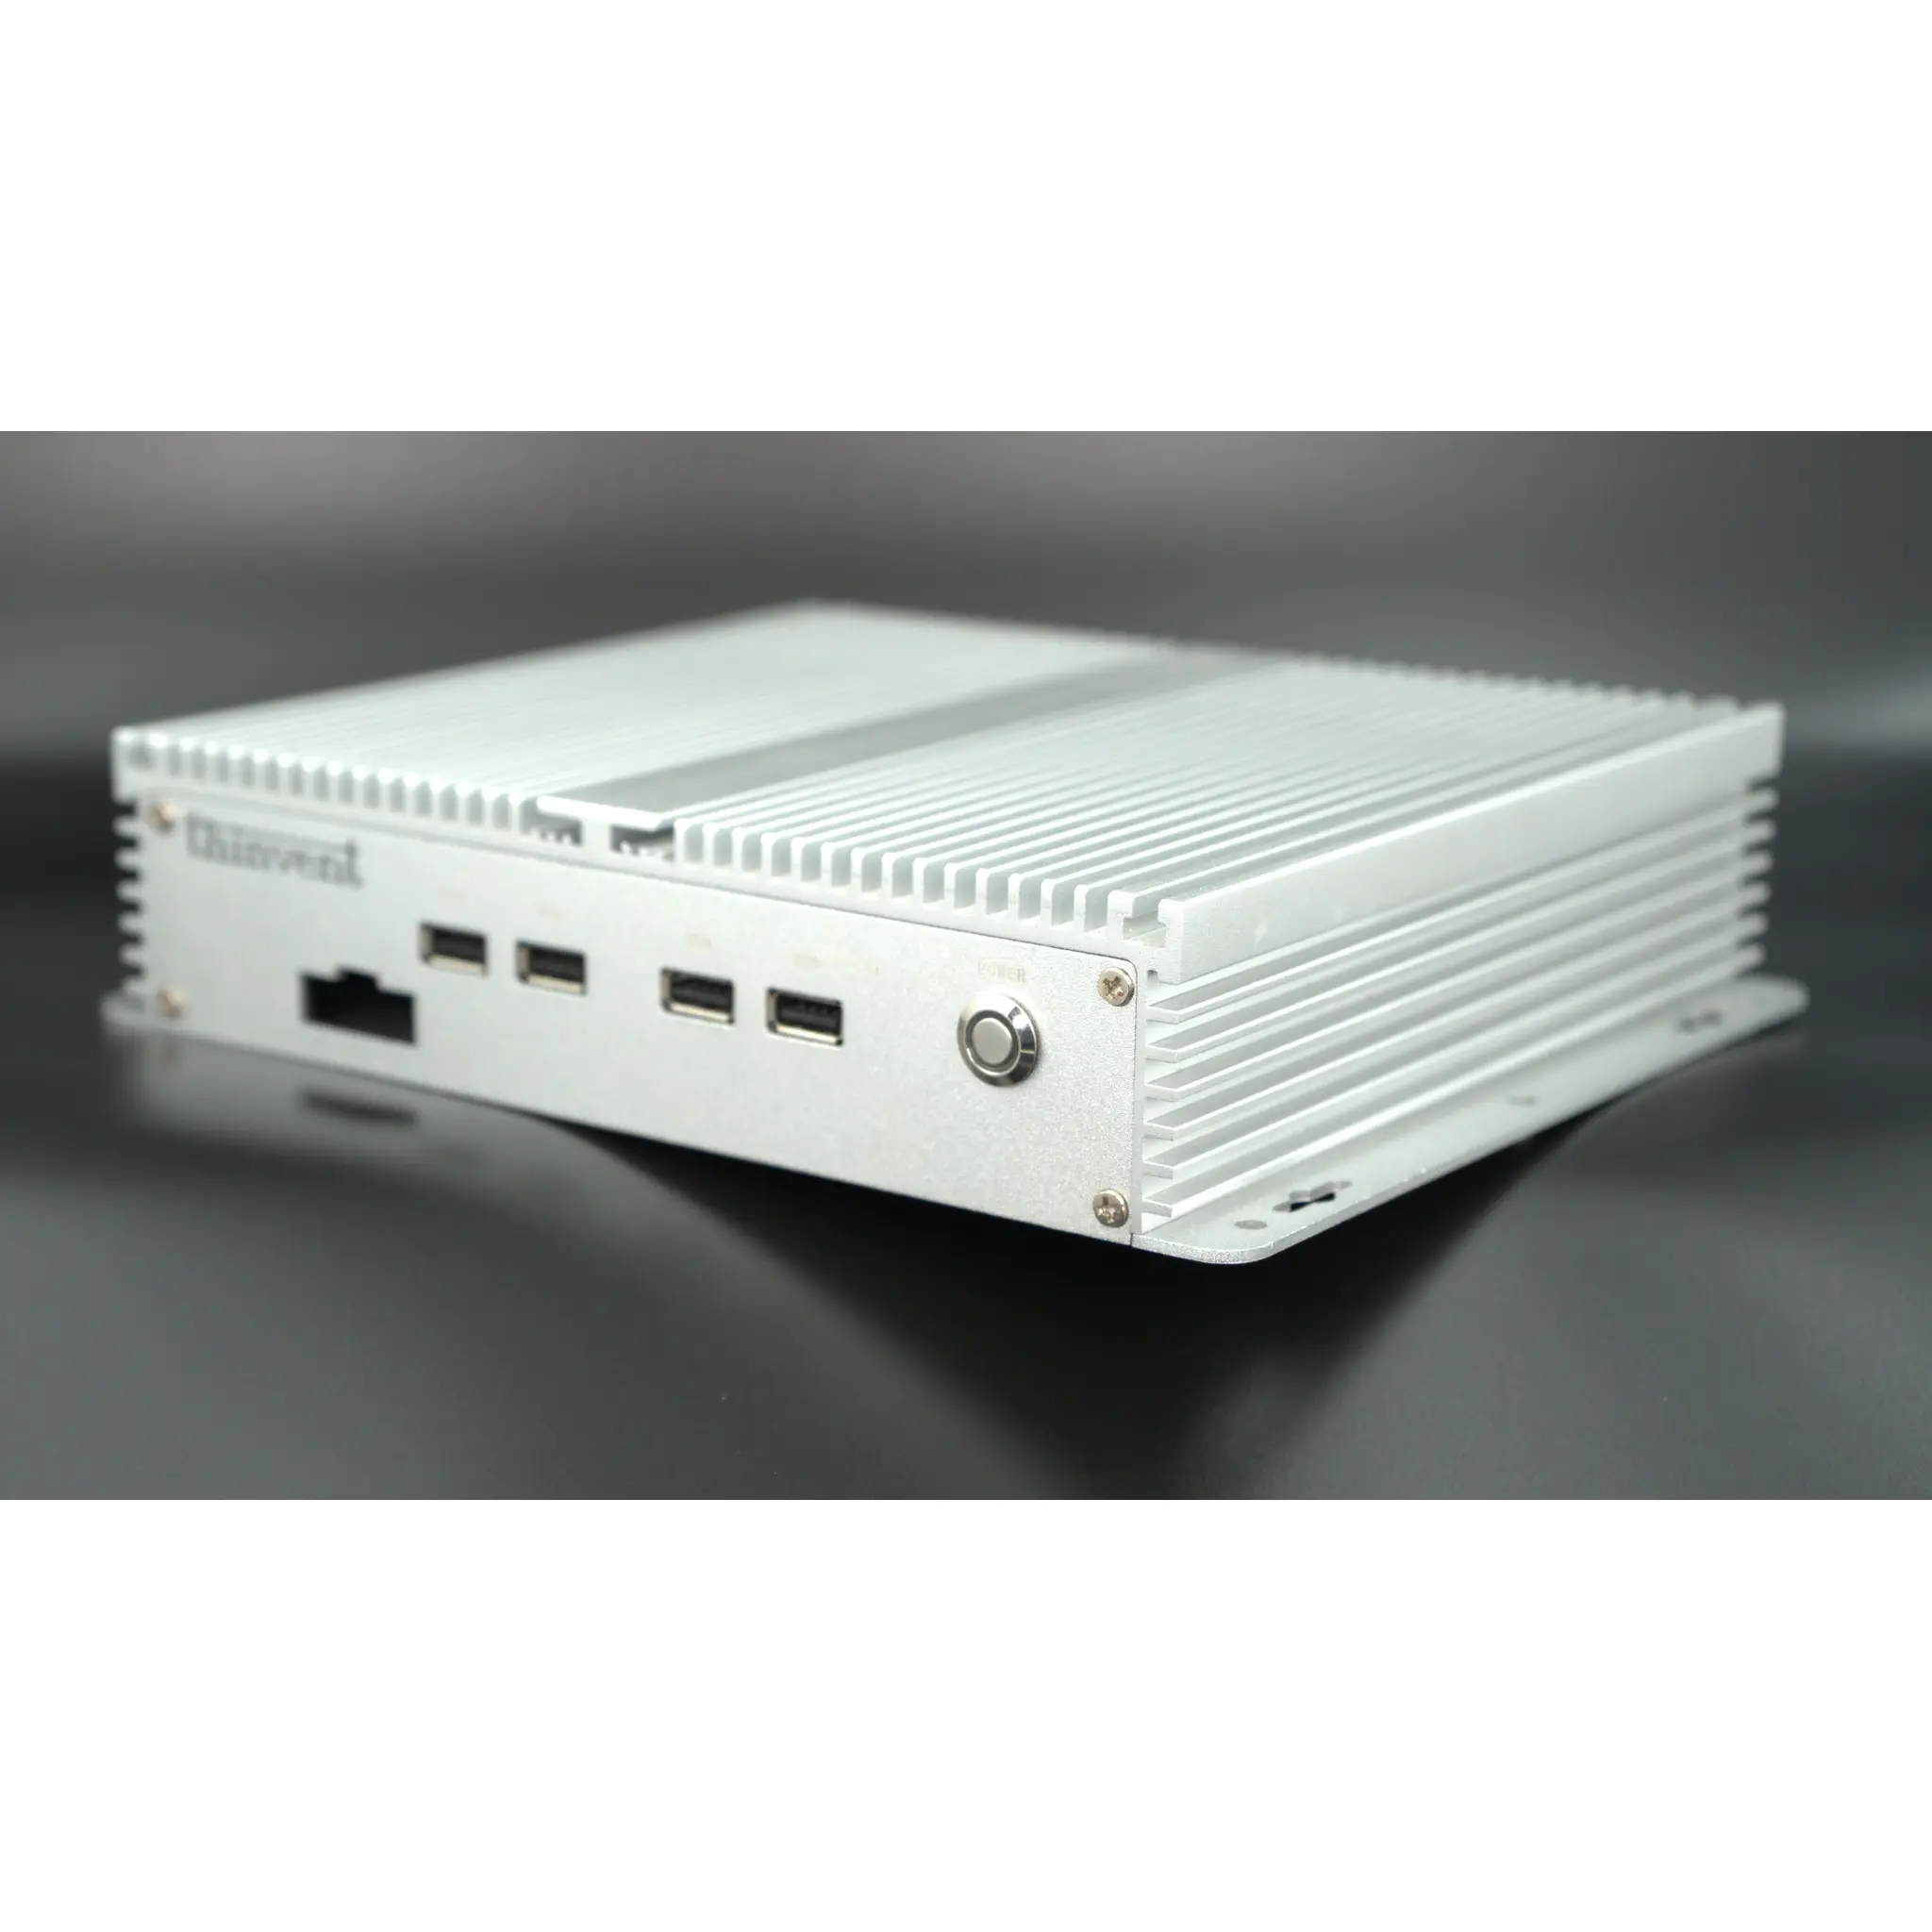
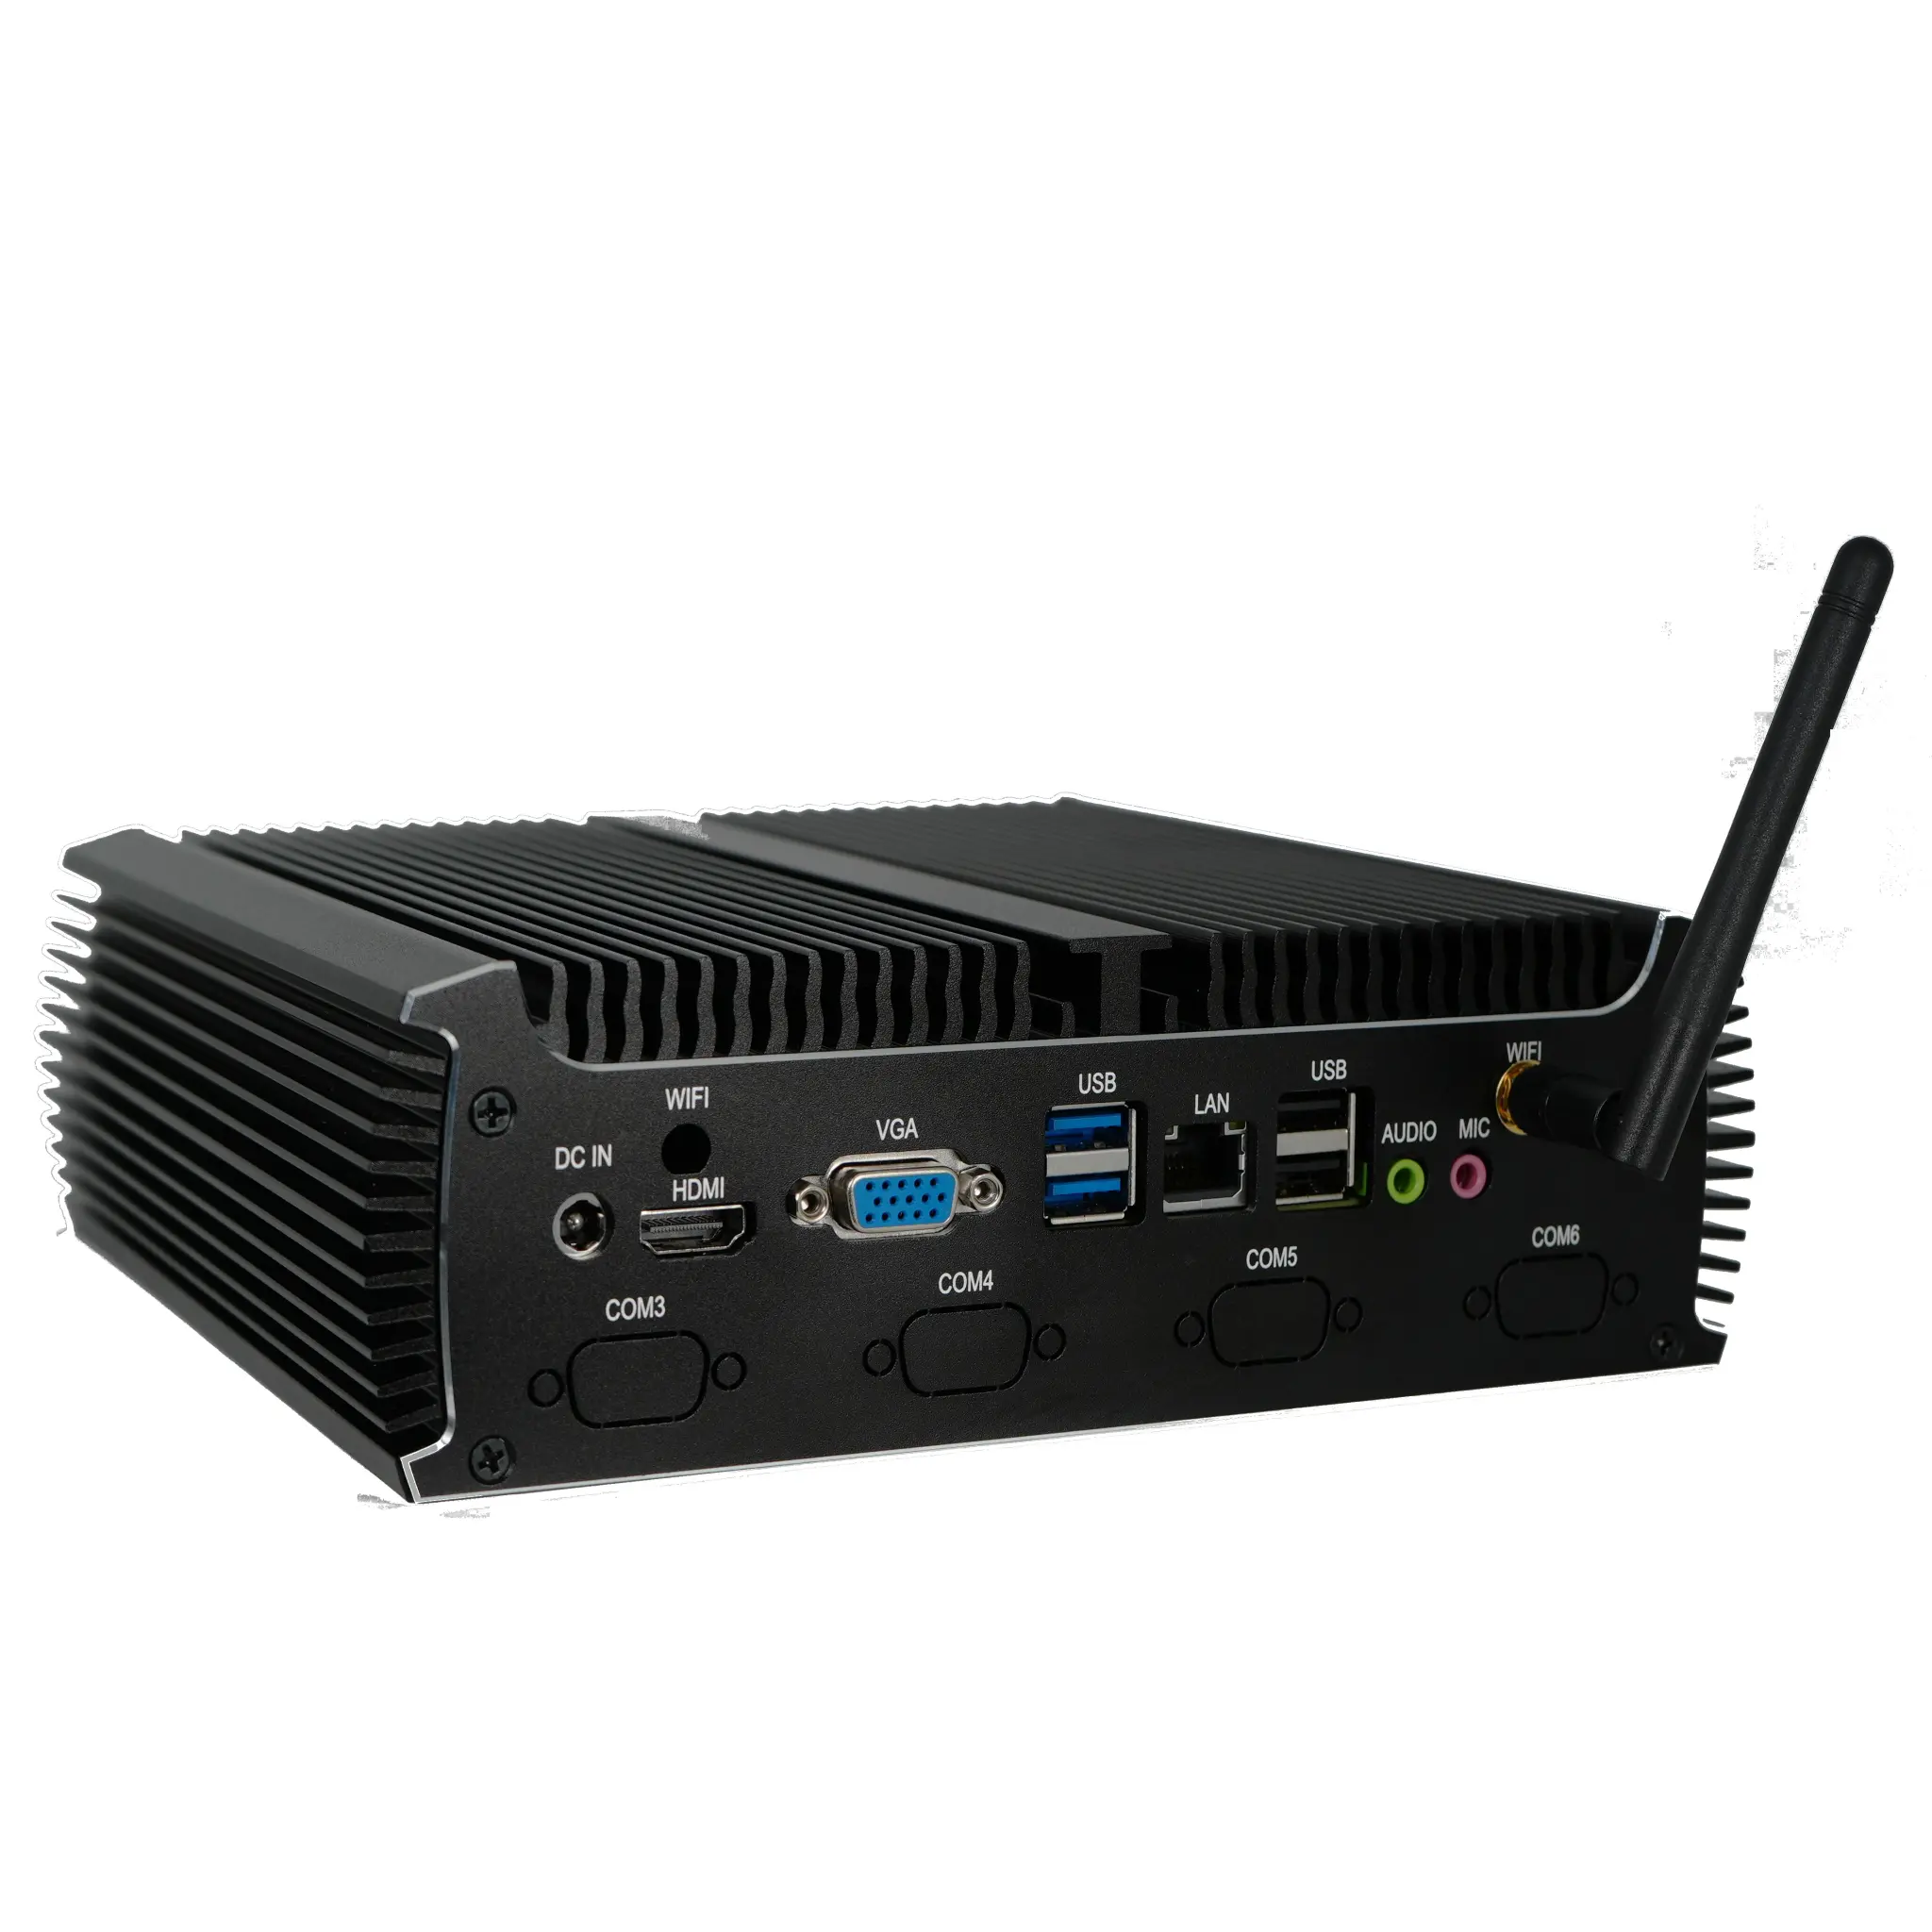
Linux is the natural home for open source AI workloads: Ubuntu 24.04 LTS and embedded Linux images ship with mature toolchains, container runtimes and Python environments, and most inference engines publish first-class Linux builds. Windows 11 Pro and Windows 11 IoT Value remain practical where the AI service must sit beside existing Windows software, with ONNX Runtime and OpenVINO providing solid CPU acceleration. A dual-boot or container-based approach lets one machine serve both worlds. Whichever path you take, prefer systems that expose standard interfaces — serial ports, Gigabit Ethernet and multiple USB ports — so cameras, sensors and PLCs connect without adapters.
Thinvent Products for Open Source AI Workloads
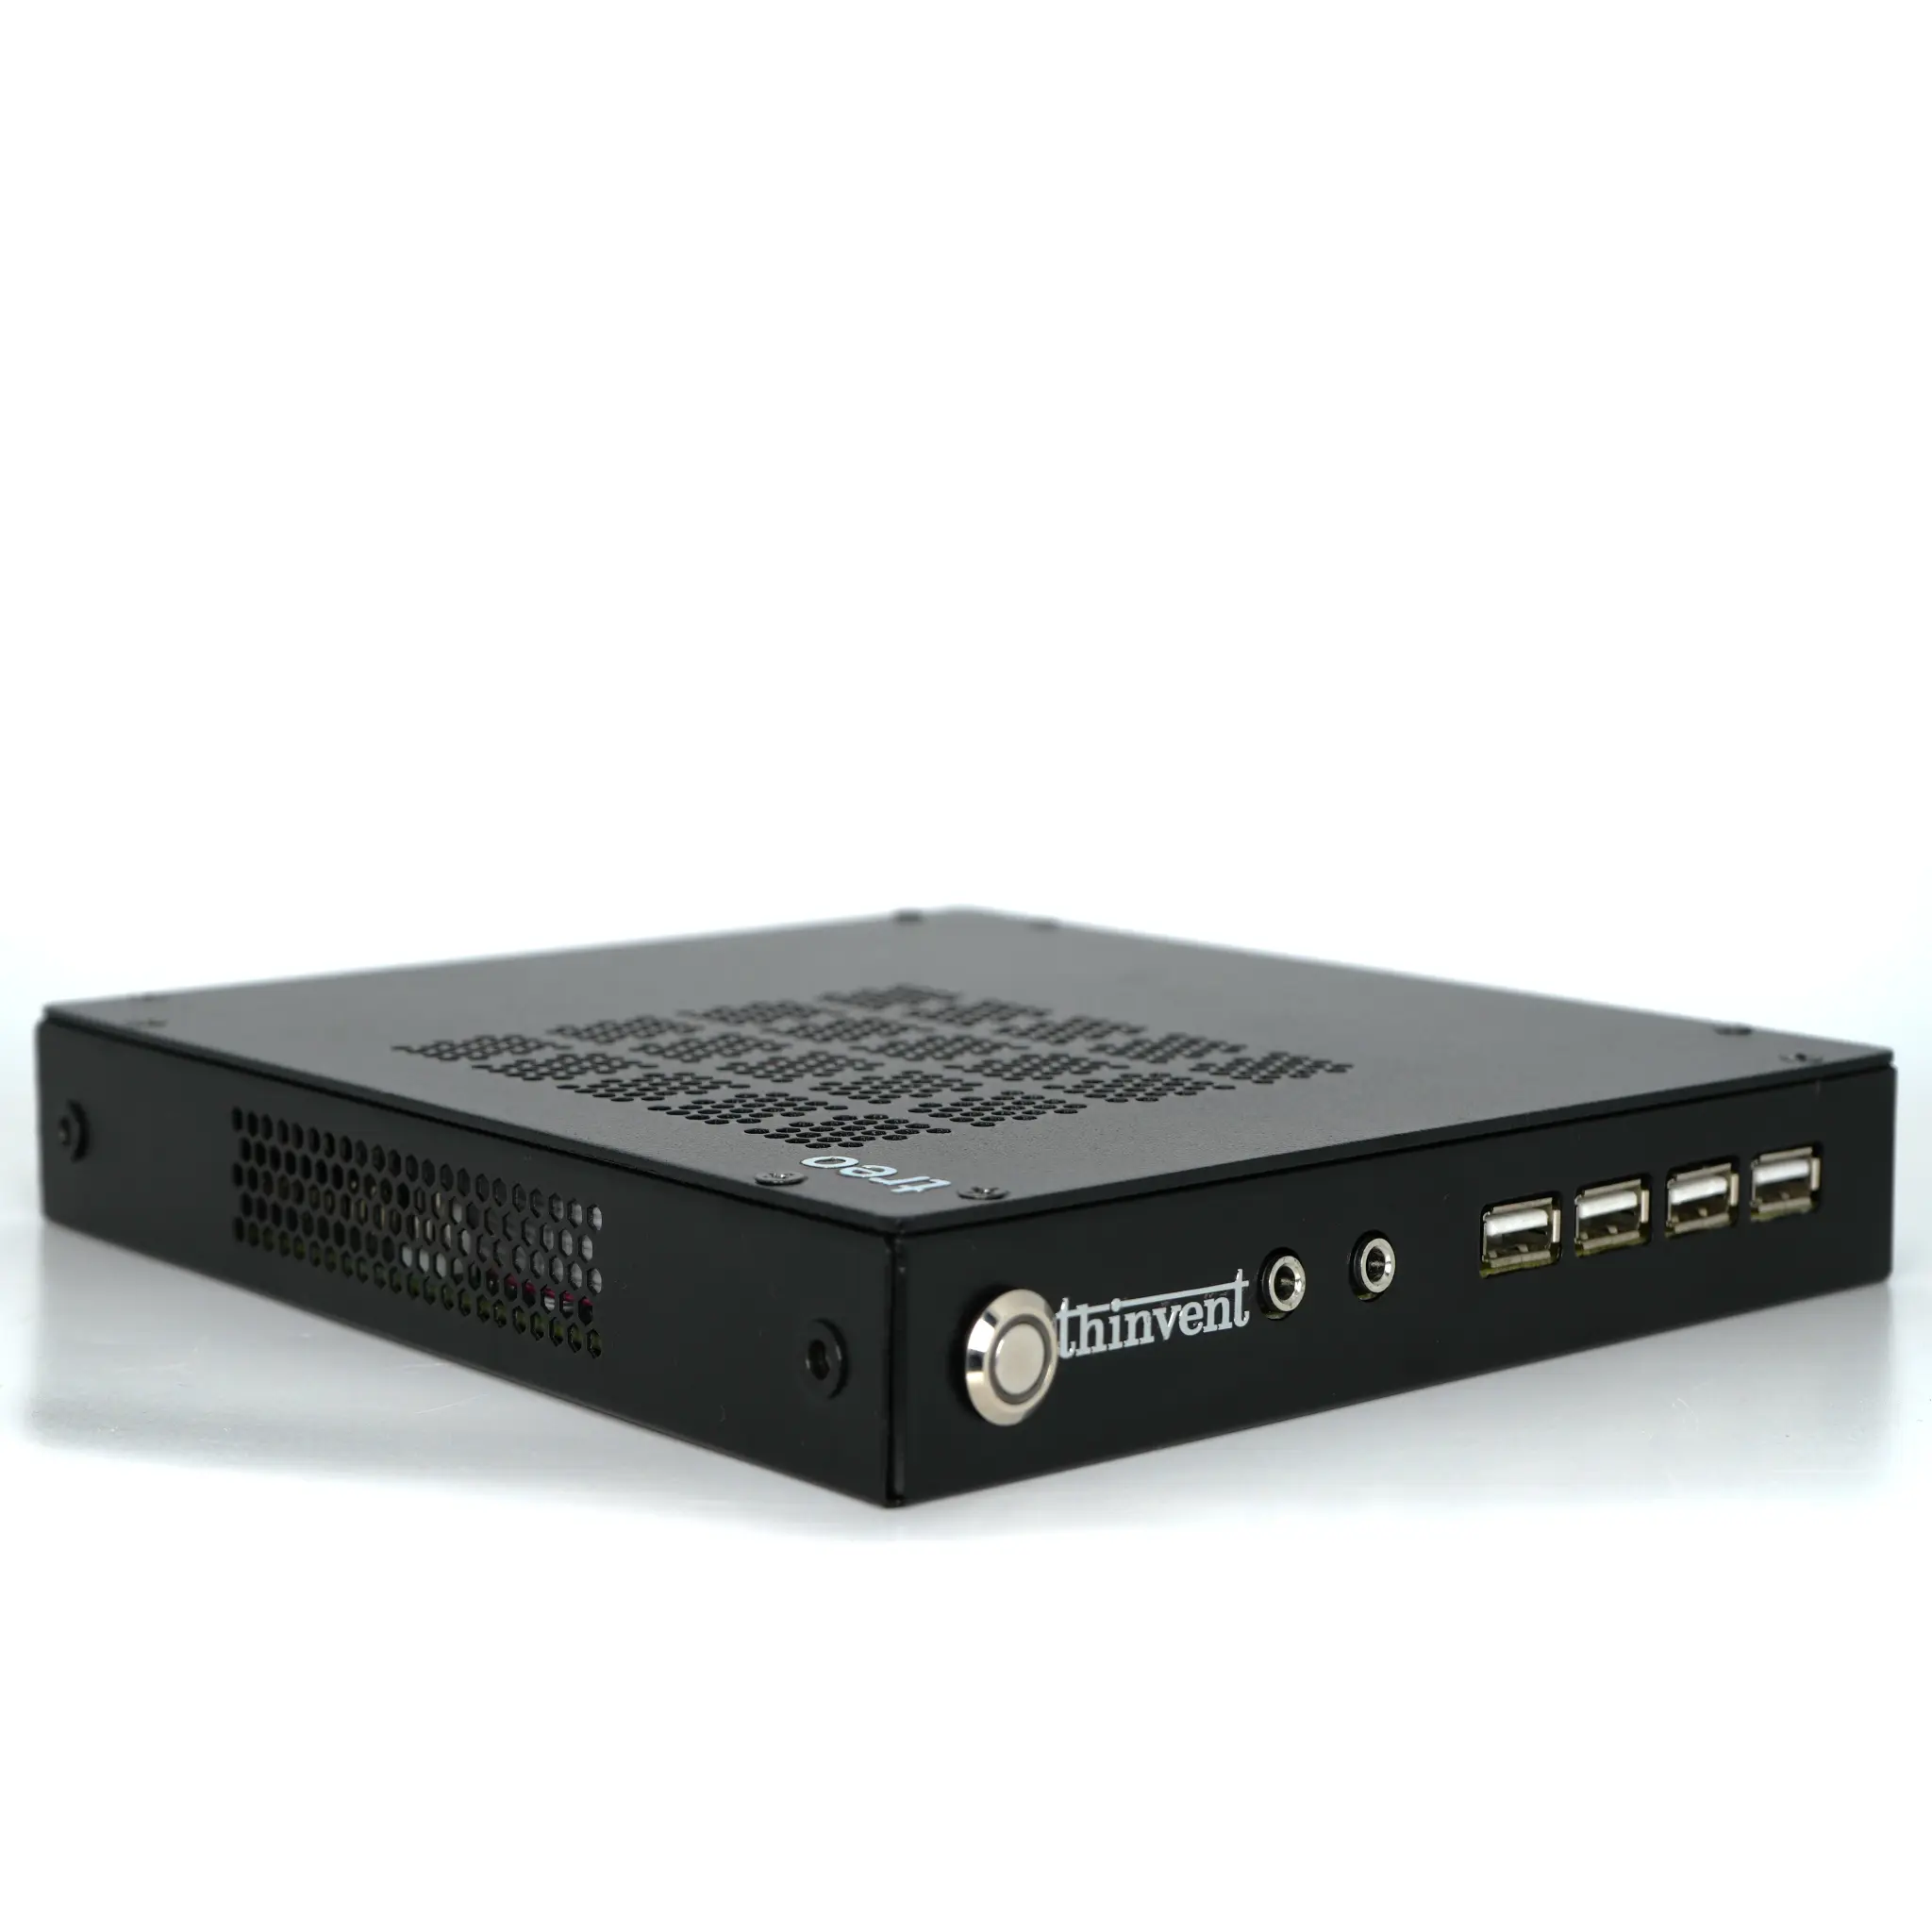
Thinvent builds industrial computers, mini PCs, thin clients and all-in-one PCs designed for exactly this class of always-on, locally hosted workload. Configurations pairing Intel® Core™ i3 or Intel® N-series processors with 8–32 GB of memory and 256 GB–1 TB SSDs provide the CPU throughput and headroom that quantised open source models need, while fanless enclosures, wide-temperature tolerance and 12 V DC inputs suit factory floors, kiosks and edge cabinets. Options for Ubuntu Linux 24.04 LTS, Thinux™ Embedded Linux, Windows 11 Pro, Windows 11 IoT Value or no OS at all let you deploy the inference stack of your choice, and dual Gigabit Ethernet plus multiple serial and USB ports make it straightforward to attach the cameras, sensors and controllers that feed your models.